Diskless Kafka: What Changes When the Data No Longer Belongs to the Brokers?
A look at diskless Kafka architectures that compares how KIP-1150, WarpStream, AutoMQ, and Redpanda approach keeping Kafka's active log in object storage.
Apache Kafka was built to take full advantage of sequential I/O. Producers group records into batches, brokers append those batches to ordered log segments, and consumers read contiguous ranges. Kafka also leans on the operating system’s page cache and, where it can, on zero-copy techniques like sendfile. As the Kafka design documentation explains, this works because batching converts lots of small operations into bigger sequential reads and writes that storage devices and operating systems handle efficiently.
The cloud offers yet another storage option. An object store delivers durable, replicated storage that is independent of broker compute. Could Kafka use such a service for the active log, allowing brokers to scale without having to move the durable dataset?
This is the concept behind diskless Kafka: keep Kafka’s client API but take durable payload storage out of the partition logs owned by brokers. The implementation must still preserve ordering, assign offsets, keep track of committed writes, and serve reads efficiently. Each system splits these responsibilities in its own way, and their feature coverage differs.
Upstream status, August 25, 2026: KIP-1150 has been accepted, but native Diskless Topics are not yet generally available in Apache Kafka. KIP-1163 and KIP-1164, which specify the core implementation, are still being discussed.
How the broker and the log are coupled
In classic Kafka, the partition leader receives records, assigns them offsets, and appends batches to local log segments. Followers fetch from the leader and append the very same batches to their own storage. With acks=all, the producer gets a successful acknowledgement only after the required replication has happened.
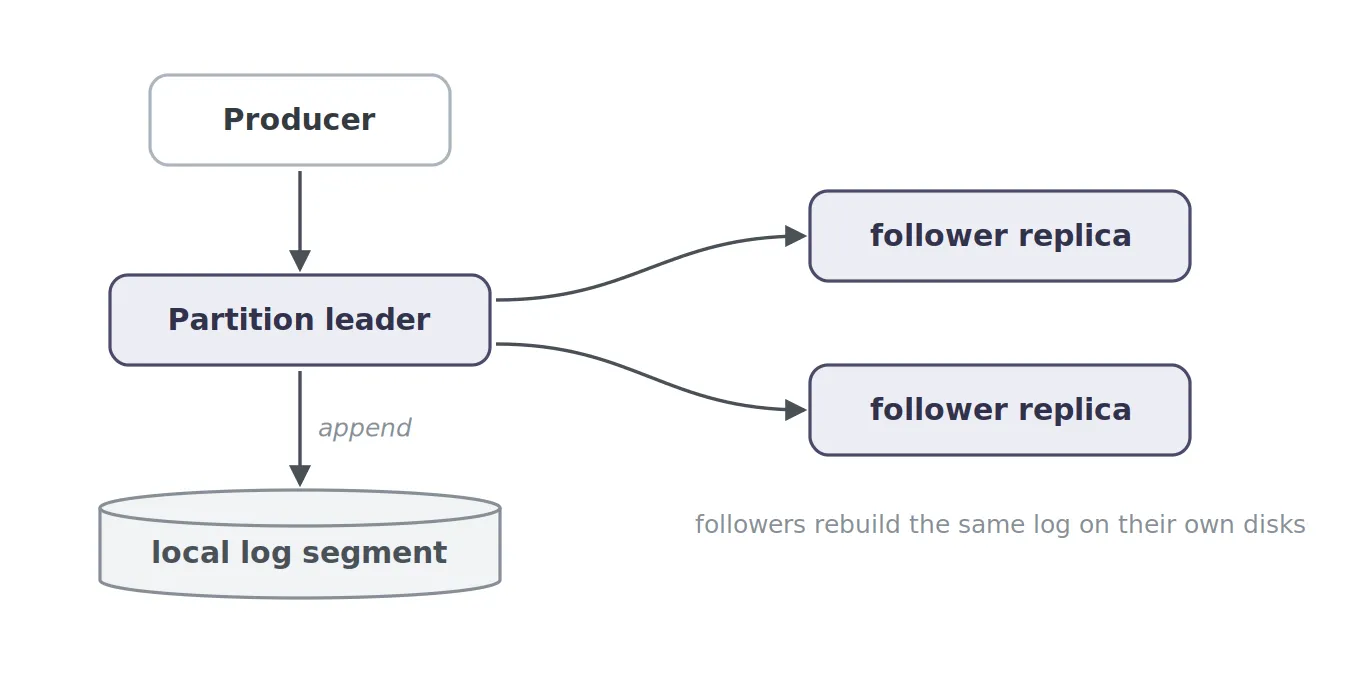
Batching cuts network and system-call overhead, and the page cache can serve recent data without reading from the physical disk. As a result, a broker is responsible both for processing its partitions and for their local log segments and replica state. Moving partitions to a different place therefore frequently means moving their data as well.
The cloud changed the storage equation
Picture a cluster that spans three availability zones. The leader stores each record, and it is copied to followers located in the other zones:
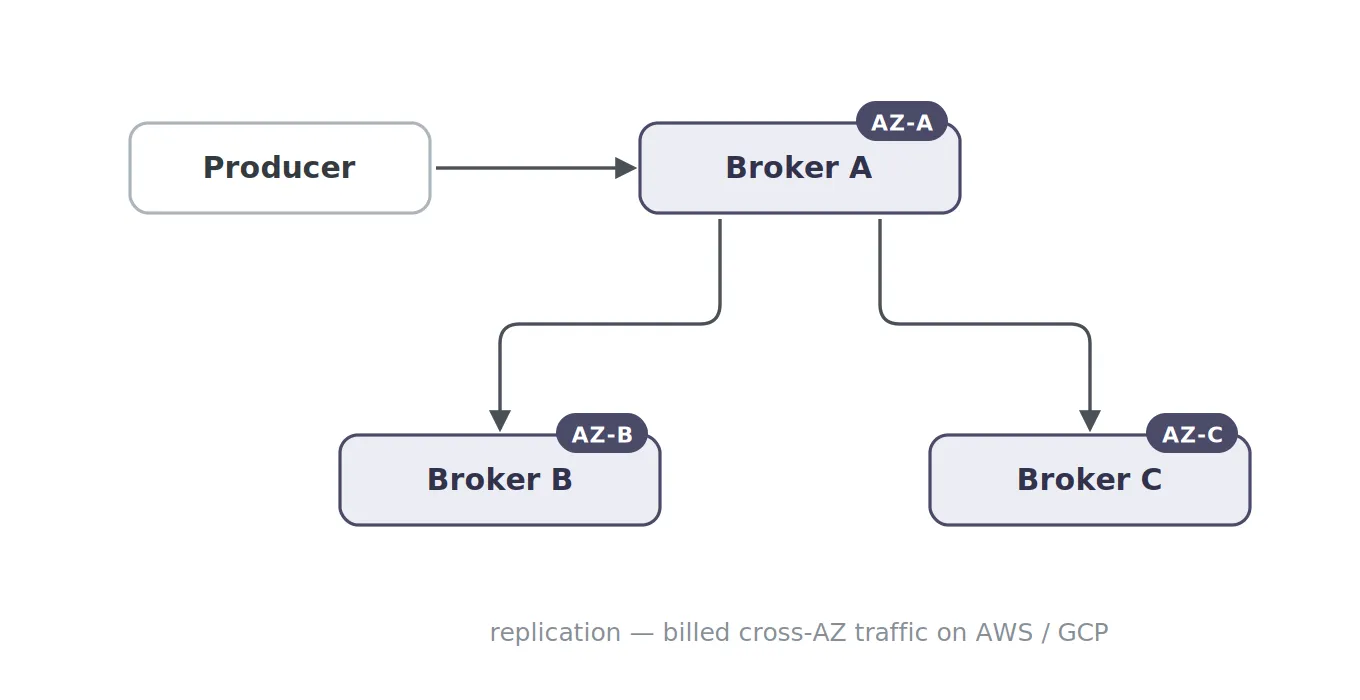
Cross-zone replication allows Kafka to survive zone failures, provided replica placement and acknowledgement settings are configured for it. It can also produce a lot of cross-AZ traffic, which KIP-1150 names as a major source of cost on AWS and Google Cloud. The exact economics vary by provider and network setup; payload replication is just one component of the overall traffic bill.
Each broker also has to have enough storage for the partitions assigned to it. Adding capacity may involve reassigning partitions, and replacing a lost replica means copying its data. A broker that holds terabytes of partition state takes longer to replace than a worker whose durable state is kept somewhere else. Storage capacity and data movement limit how fast compute can be changed.
Amazon S3, Google Cloud Storage, and Azure Blob Storage offer durable storage that does not depend on Kafka brokers. With a suitable regional storage class, the provider also takes care of replication across failure domains. The meaningful comparison is between such a service and Kafka’s entire replicated storage path. EBS on its own replicates inside a single availability zone; Kafka’s replicas can stretch that protection across zones.
KIP-1150 suggests handing payload durability over to object storage in order to cut the cost of replicating active segments and of broker block storage. What changes is who is responsible for replication, and which data still has to go through Kafka’s coordination mechanisms.
Diskless Kafka vs. Tiered Storage
Kafka already makes use of object storage via Tiered Storage. Finished log segments can be copied to remote storage and then deleted from the local tier. The active segment, however, still sits on broker storage, and followers still replicate incoming records.
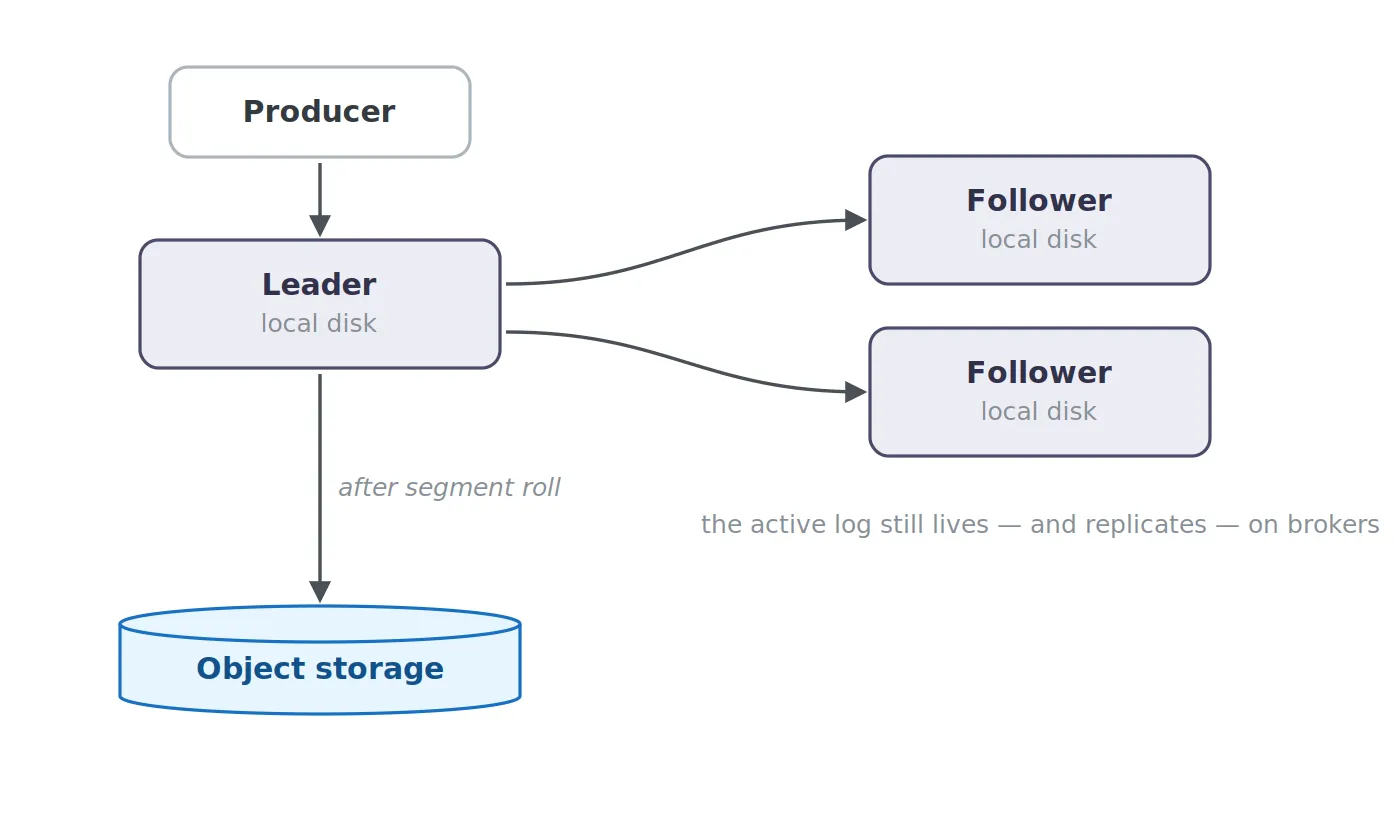
Tiered storage decouples retention from local disk capacity, so a cluster can keep months of history without sizing broker disks for the whole dataset. Diskless storage goes further and changes the active write path too:
| Classic Kafka | Kafka with tiered storage | Direct-to-object-storage diskless path | |
|---|---|---|---|
| Active payload | Logs on brokers | Logs on brokers | Shared objects |
| Payload replication | Kafka followers | Kafka followers | Storage provider |
| Historical payload | Logs on brokers | Remote segments plus a local tier | Shared objects, frequently reorganized for reads |
| Producer acknowledgement depends on | The broker append and the configured acknowledgements | The same active path as in classic Kafka | Persisting the object and committing metadata |
Some systems put a separate WAL in front of the object-storage dataset. In such designs, the WAL decides when a write may be acknowledged; we will cover AutoMQ below.
What “diskless” means
The term is a bit misleading. Diskless doesn’t have to mean there is no disk anywhere in the system; its meaning is narrower: the broker’s local disk stops being the primary durable source of truth for user data. KIP-1150 phrases it well: diskless relates to “no disks” in roughly the same way serverless relates to “no servers.” Disks can still be there for caches, metadata, or temporary state, but they are no longer the storage abstraction operators have to manage for the message payload itself.
Here is a simplified diskless write path:
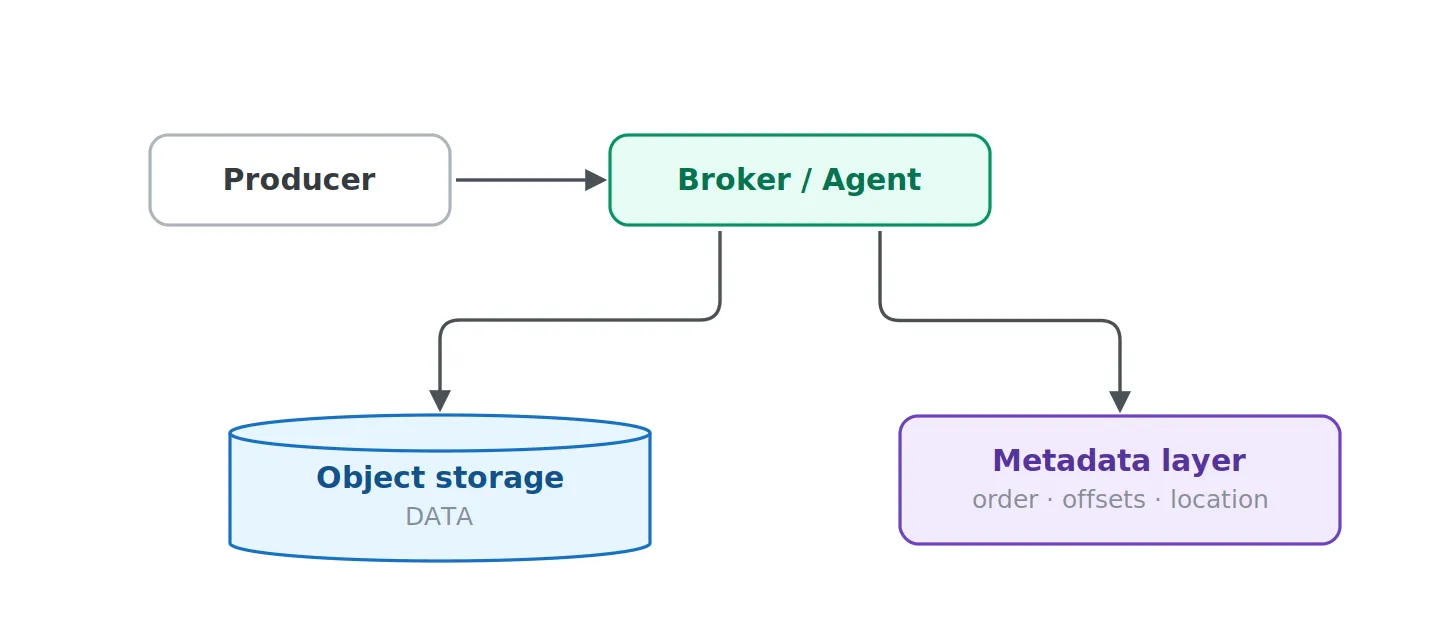
Classic Kafka stores payloads together with their ordering in partition logs. Diskless systems split the two: object storage keeps the bytes, and metadata determines their order, offsets and commit status.
S3 is not a Kafka log
At first sight, putting Kafka on top of object storage seems trivial: take a record, write it to S3, and you’re done. Sadly, that would make for an awful streaming architecture. Object stores are optimized for objects rather than appendable logs – typically you create immutable objects and fetch them later – and their operations come with non-trivial latency and a cost per request.
Writing a separate S3 object for each Kafka record would get expensive very fast at high throughput. One per producer batch? Still way too many objects. One object per partition every few hundred milliseconds? Then a cluster with tens of thousands of partitions begins producing an unpleasant volume of tiny objects and PUT operations.
What object storage prefers:
FEWER
LARGER
OBJECTS
What Kafka prefers:
MANY
INDEPENDENT
ORDERED PARTITIONS
Diskless streaming becomes interesting precisely in reconciling these two sets of needs.
How diskless Kafka batches across partitions
Most diskless Kafka architectures land on the same initial optimization: rather than creating an object per partition, batch data from many partitions together.
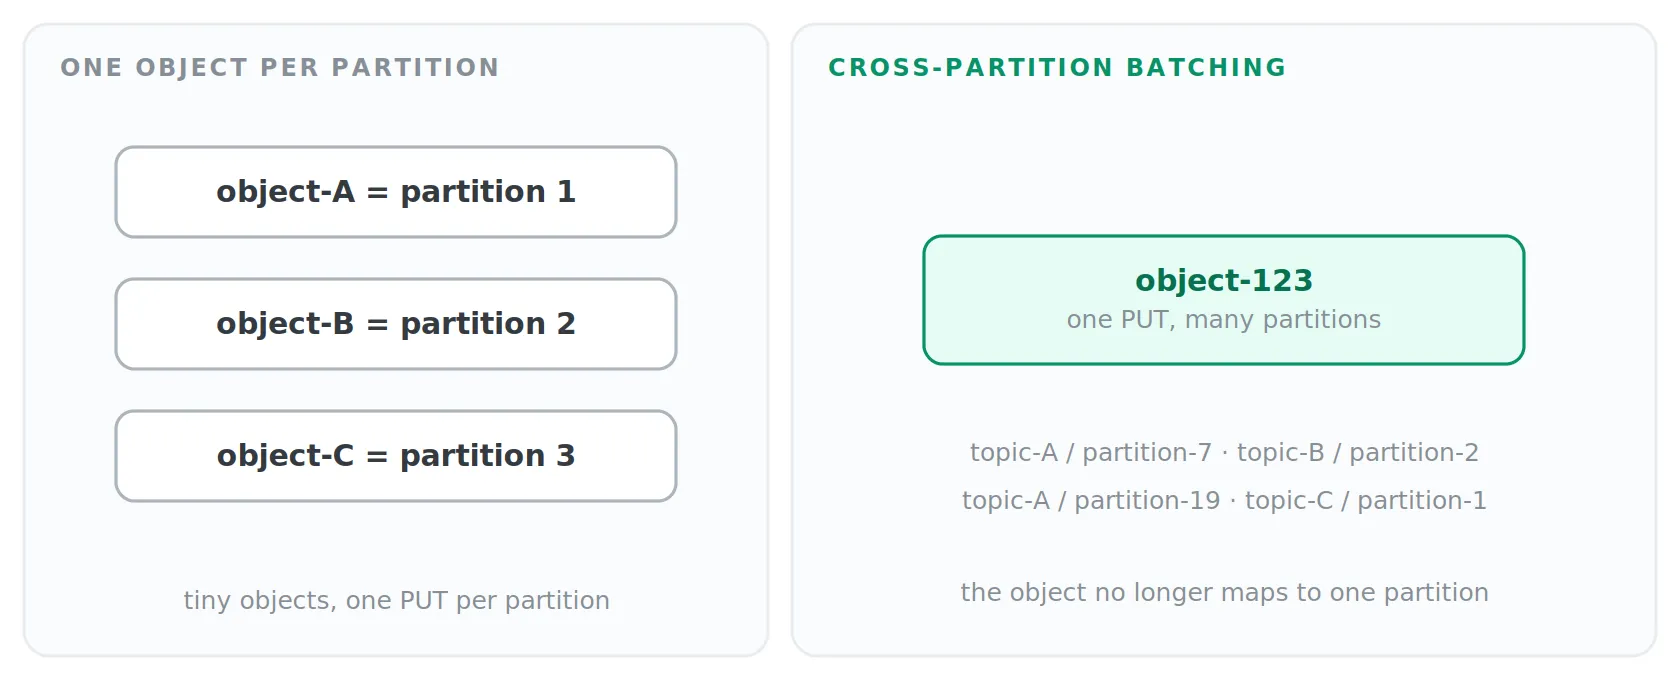
WarpStream illustrates this well. Its Agents buffer producer traffic coming from many clients and partitions and flush it once a time or size threshold is reached; by default, the batch timeout is currently 250 ms. To be exact about what that figure means: it is the maximum time an Agent waits for a batch to fill up, not the durable write latency – under real load, the size threshold is usually hit first, and the producer acknowledgement also has to wait for the object-storage upload and the metadata commit. The 250 ms is a single part of a latency budget we will come back to later in the article.
A single file may hold records from many different topic-partitions. The object is persisted first, then its metadata is committed, and only after that is the produce request acknowledged. Aiven’s diskless implementation follows the same general idea, and Redpanda Cloud Topics batches data across topics and partitions into so-called L0 objects – “level zero,” a name taken from LSM-tree storage engines for raw, freshly ingested files – before storing lightweight metadata in Raft. Remember this term; the levels will come up again.
Several teams reached this design on their own because cross-partition batching spreads the cost of an object-storage operation over a worthwhile amount of data. The downside is that a physical object no longer corresponds neatly to a Kafka partition.
The physical Kafka log just disappeared
In classic Kafka, partition-7.log holds the records of partition 7, in order. The physical storage layout and the logical Kafka log are tightly linked. Now look at our diskless object:
object-123

P7 | P2 | P19 | P1 | P7
and at another broker writing at the same time:
object-124

P1 | P7 | P5 | P19
Which P7 batch is first? Object names can’t tell us, the time an upload completed isn’t sufficient, and the object itself can’t tell us either. Object storage holds bytes, but the Kafka abstraction demands more: topic, partition, offset, order. A diskless system therefore needs an additional structure that maps the logical log onto physical storage – roughly like this:
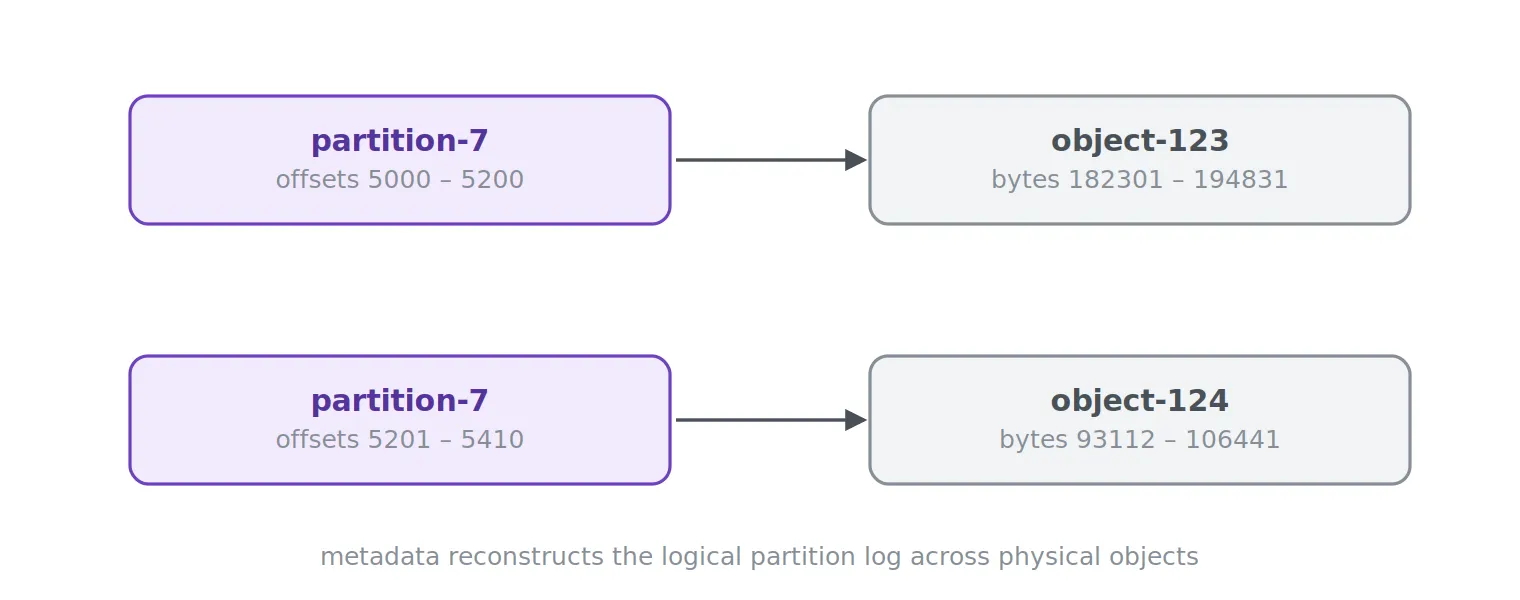
Having removed the physical partition log, we now need to rebuild a logical partition log from metadata. Note what we are really constructing here: a log that exists purely as strongly consistent metadata on top of shared objects – in other words, a distributed database speaking Kafka’s protocol.
Metadata defines the committed log
Ordering is metadata. Assigning offsets is metadata. The mapping between offsets and object locations is metadata. Transactions require metadata, idempotent producers require state, retention ultimately alters metadata, compaction alters metadata, and garbage collection relies on all of the above. A diskless Kafka implementation can hand off replication of message payloads to S3, but it cannot hand off Kafka semantics to S3. In other words, diskless Kafka doesn’t eliminate consensus – it moves it somewhere else. Payload durability may shift into object storage, yet the system still needs a strongly consistent place that decides what sits at each offset and which writes are committed.
A reasonable objection comes up at this point: isn’t the metadata layer just the original replication problem in a new guise? In part, yes – and none of these designs claims otherwise. The metadata store is a replicated, strongly consistent system in its own right, and it handles a commit for every batch, so the count of coordination operations stays the same. What differs is the content of each operation: a pointer-sized record describing an object and its offset ranges rather than the payload. Cross-AZ traffic is charged per byte rather than per operation, so reducing the replicated unit from megabytes of records to a single metadata entry is precisely where the savings come from – and cross-partition batching keeps the commit rate tied to batches rather than to individual records. Diskless Kafka doesn’t avoid replication; it limits it to the data that is small and truly requires consensus. Later in this article, Apache Kafka’s own proposal arrives at the same conclusion: the diskless coordinator stores its state in a replicated internal Kafka topic.
Different implementations, different boundaries
“Diskless Kafka” is turning into a category instead of a single specific architecture. Every implementation below moves the payload out of Kafka’s traditional replicated local log, but they keep varying amounts of state in brokers and add different metadata paths.
| System | Durable payload path | Ordering / metadata path | Broker model |
|---|---|---|---|
| WarpStream | Straight to object storage | A dedicated, strongly consistent metadata store | Stateless Agents |
| AutoMQ | WAL first, then object storage | S3Stream / Kafka metadata | Stateless brokers |
| Redpanda Cloud Topics | Object storage | Per-partition Raft placeholders plus a shared metastore | Stateful metadata, payload in the cloud |
| Confluent Freight | Direct writes to object storage | Kora internals | Managed implementation |
| Aiven Diskless | Object storage | Batch Coordinator | Leaderless data path |
| Apache Kafka proposal (KIP-1163) | Object-storage WAL segments, later merged into objects | The proposed Diskless Coordinator | A planned hybrid topic model |
WarpStream: write directly to object storage
WarpStream arguably implements the idea in its purest form. Its Kafka-compatible Agents need no local disks: they write straight to object storage, and metadata is kept in WarpStream’s separate metadata layer. Since no Agent owns durable partition data, compute nodes can be added or removed without relocating the stored log.
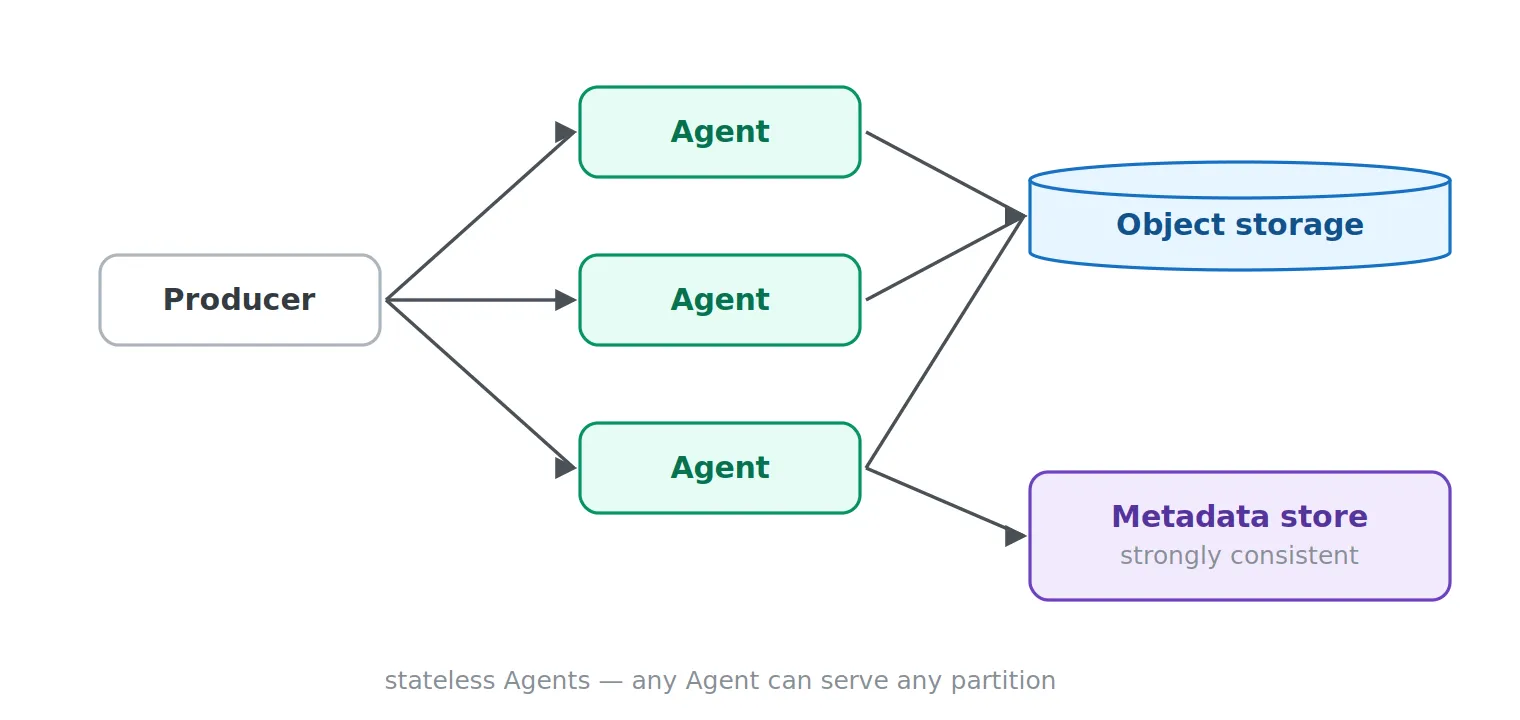
Every Agent can serve every partition, which breaks the usual link between partition ownership and durable storage. The trade-off is just as straightforward: object storage is part of the acknowledgement path, so latency and the economics of object-store requests become primary design constraints. WarpStream describes the architecture in its write-path and read-path guides.
AutoMQ: add a WAL
AutoMQ opts for a different compromise. It accepts that object storage should keep the actual dataset, but adds a WAL to speed up persistence and recovery:
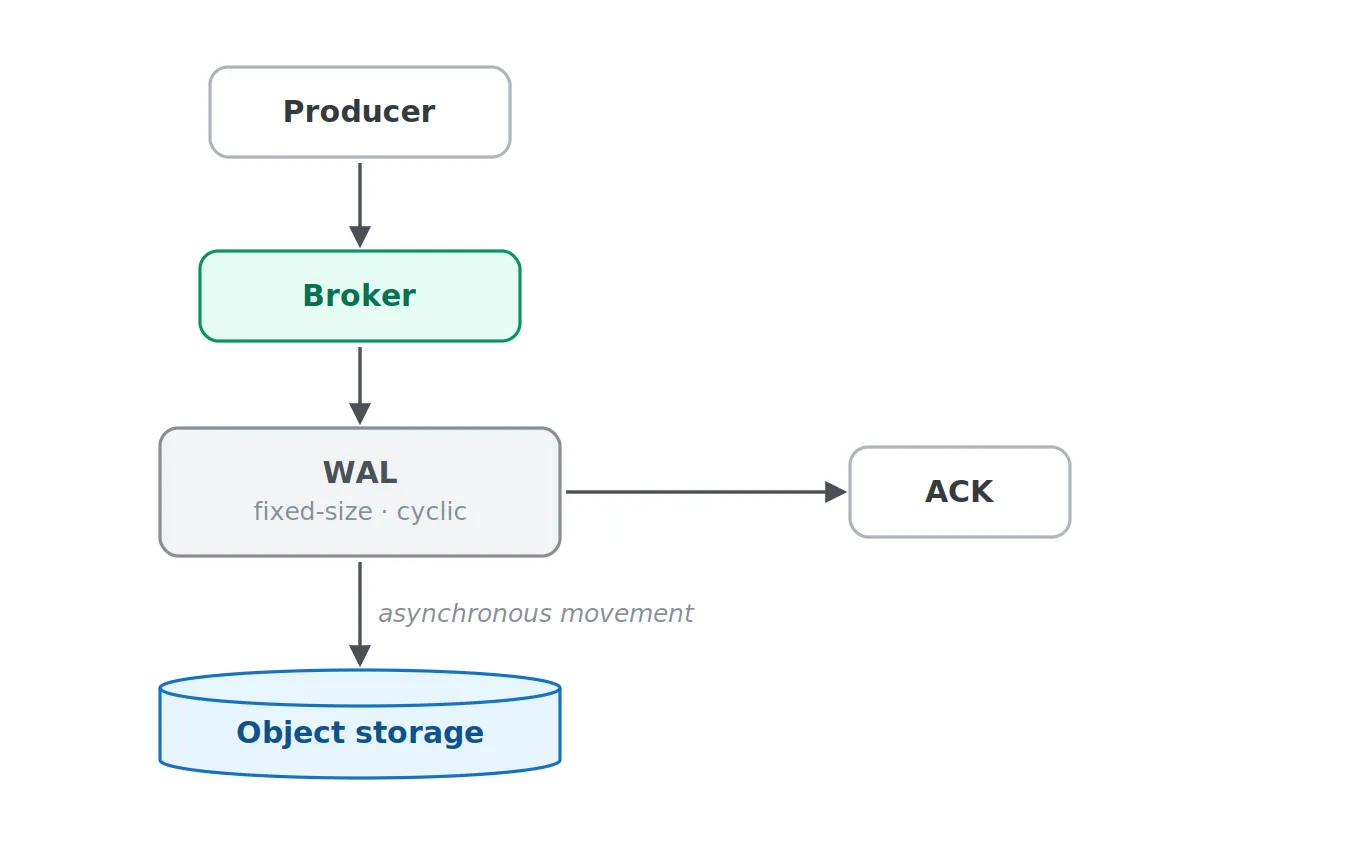
Interestingly, the WAL is shared by writes from many partitions instead of preserving Kafka’s traditional per-partition log structure. According to AutoMQ, it is fixed-size and cyclic, using sequential writes and group commits. So even once Kafka has moved away from partition logs owned by brokers, the same optimization resurfaces at a different layer. Object storage changes the location of the durable dataset; it doesn’t cancel out the benefits of sequential I/O.
The obvious next question is how the WAL itself gets replicated – and the answer is that AutoMQ intentionally doesn’t replicate it. Its declared design principle is to rely on cloud storage for durability rather than running a replication protocol like Raft: with an EBS-backed WAL, durability comes from the volume’s built-in replication, and if a broker fails, its orphaned volume is just attached to another broker, which flushes the outstanding WAL entries to S3; with an S3-backed WAL (the open-source default), the WAL objects already live in object storage, so a new broker recovers them directly. AutoMQ does use consensus – but only in the same place as every other system in this article: the metadata plane, where AutoMQ reuses Kafka’s KRaft.
Redpanda Cloud Topics: retain per-partition Raft metadata
Redpanda follows a hybrid approach it calls “disk-lite”: payloads land in object storage, while critical metadata still passes through local Raft.
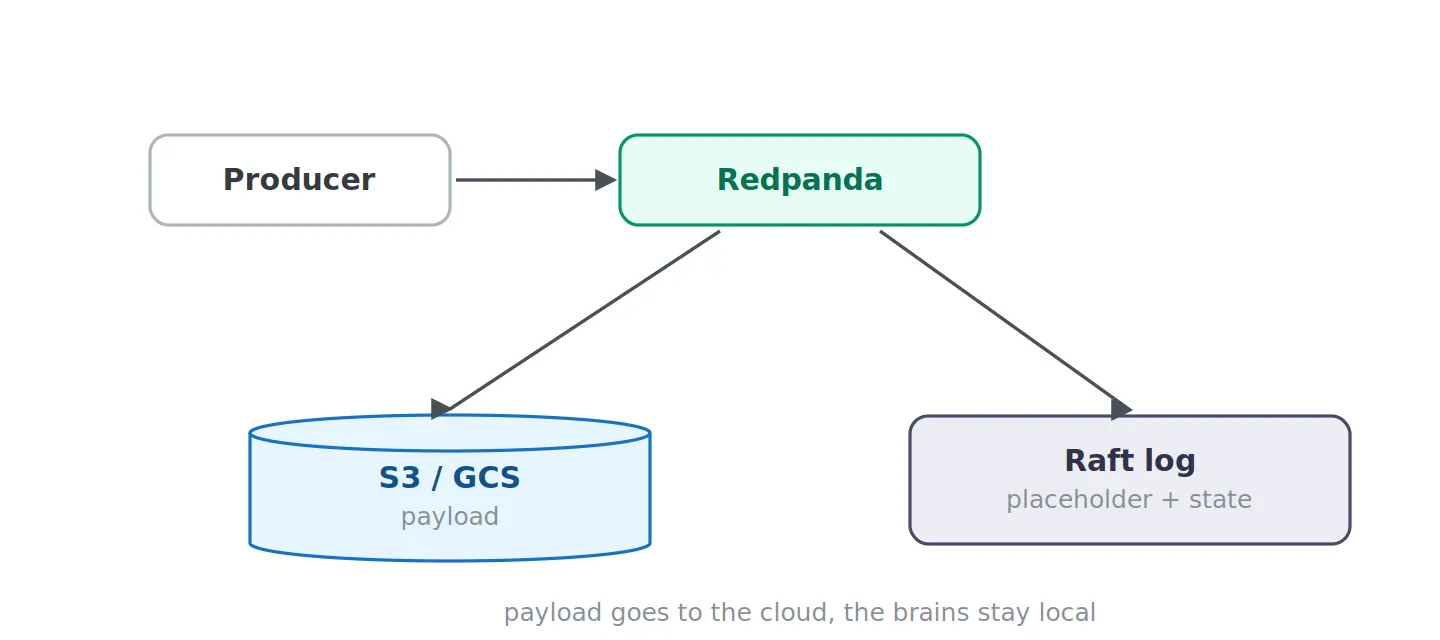
When an L0 object becomes durable, Redpanda writes placeholder metadata to the Raft log of the relevant partition and then acknowledges the producer. Consider what this means for broker state: the placeholder log is still a per-partition Raft log hosted on particular brokers, so each broker stays a member of specific Raft groups and holds local metadata state, votes, and leadership roles. That state is small – pointers instead of payloads – but it makes a Redpanda broker less interchangeable than a WarpStream Agent, since an Agent holds no partition state whatsoever; its metadata sits entirely in the separate metadata service. This is what it means that Redpanda’s model keeps more state in the brokers – an intentional trade-off, as keeping the metadata log inside brokers allows Redpanda to reuse its existing transaction, idempotency and consistency machinery. Cloud Topics reached general availability in Redpanda 26.1 in 2026 and can run alongside local and tiered storage modes within one cluster.
Confluent Freight: direct write for throughput-oriented workloads
Confluent has, independently, headed the same way. Freight clusters rely on a direct-write mode in the Kora engine, in which payload data goes to object storage rather than first being durably replicated across broker-local storage. Confluent targets Freight at high-throughput workloads like logs, observability and analytical ingestion, deliberately giving up sub-100 ms latency in exchange for write paths that may take up to about one or two seconds.
Aiven Diskless: a separate Batch Coordinator
Aiven operates the Inkless implementation, whose contributors are also involved in the upstream diskless KIPs. Its payload write path has no leader: brokers upload batched records, and a Batch Coordinator assigns offsets and keeps track of where they are stored. For this coordination layer Aiven uses PostgreSQL, in contrast to the internal Kafka topic and local SQLite state proposed upstream. See Aiven’s architecture.
Classic and diskless topics can live side by side in the same Standard Kafka service. Aiven documents limited availability on Aiven Cloud and support on chosen -inkless BYOC plans. The implementation has significant feature limitations: transactions, compacted diskless topics, and Kafka Streams state stores are not supported. A classic topic can be converted to diskless via the documented migration path, but converting back is not supported. See the overview, limitations, and migration guide.
What Apache Kafka proposes
Probably the strongest signal that this architecture is significant is KIP-1150: Diskless Topics. The Apache Kafka community set its status to Accepted on March 2, 2026. Acceptance is a decision about where Kafka is heading, not a delivered feature: Kafka should support topics whose user payload is stored durably in object storage rather than relying on broker block storage and direct payload replication.
The implementation design is still in progress. As of August 25, 2026, both KIP-1163: Diskless Core and KIP-1164: Diskless Coordinator have the status Under Discussion. KIP-1165, which deals with object compaction for diskless data, had been discarded earlier but was re-opened in July 2026 and is Under Discussion once more. KIP-1176, an alternative that preserved more of the classic replication path, is Withdrawn; KIP-1183, a wider shared-storage abstraction put forward by AutoMQ contributors, is still a separate proposal Under Discussion. An overview of this entire family of proposals is kept by the community on the Saving Cross-AZ Replication Costs KIPs wiki page.
This difference is important for anyone assessing Apache Kafka itself: KIP-1150 has been accepted, yet native upstream Diskless Topics are not a generally available feature of Kafka 4.3 today.
KIP-1163 outlines a fascinating write path: brokers can buffer batches from several diskless partitions, assemble a shared WAL segment, upload it to object storage, and then commit to the coordinator the coordinates describing those batches; the coordinator assigns the global partition ordering and offsets. Conceptually:
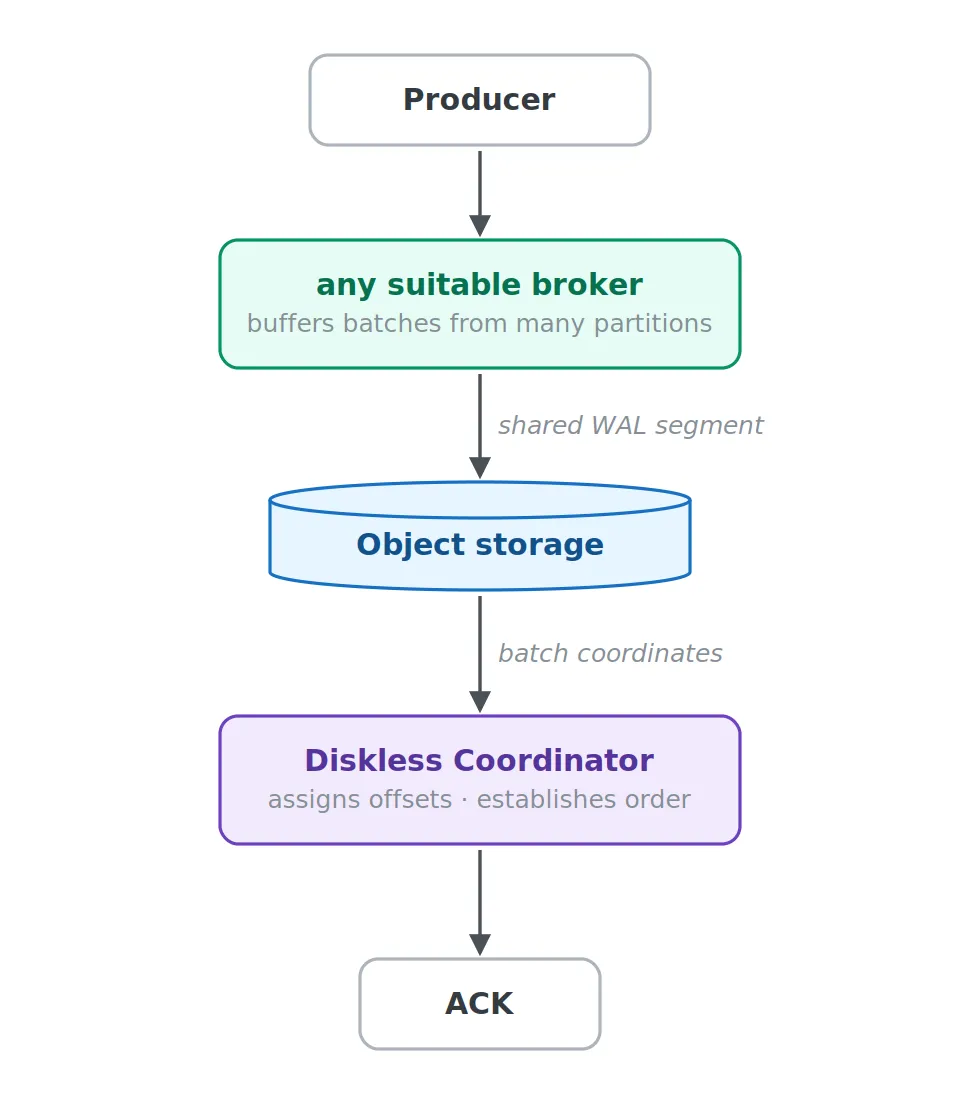
There is some historical irony in this. Kafka began with a beautifully simple storage model: the log file is the log. In the proposed diskless path, objects hold the bytes, and metadata determines how those bytes form a Kafka log.
Why the proposed coordinator uses SQLite
KIP-1164 includes one of the most telling details of the entire diskless Kafka design. The proposal adds an internal Kafka topic, __diskless_metadata, which serves as the source of truth for diskless metadata. The coordinator state is expected to reach hundreds of megabytes or even gigabytes, so holding all of it in memory is not appealing. For that reason, the proposal materializes the metadata log into a local SQLite database to allow indexed access. Kafka stays the durable source of truth, while SQLite is a local state store that can be rebuilt.
A possible future Kafka broker might therefore look something like this:
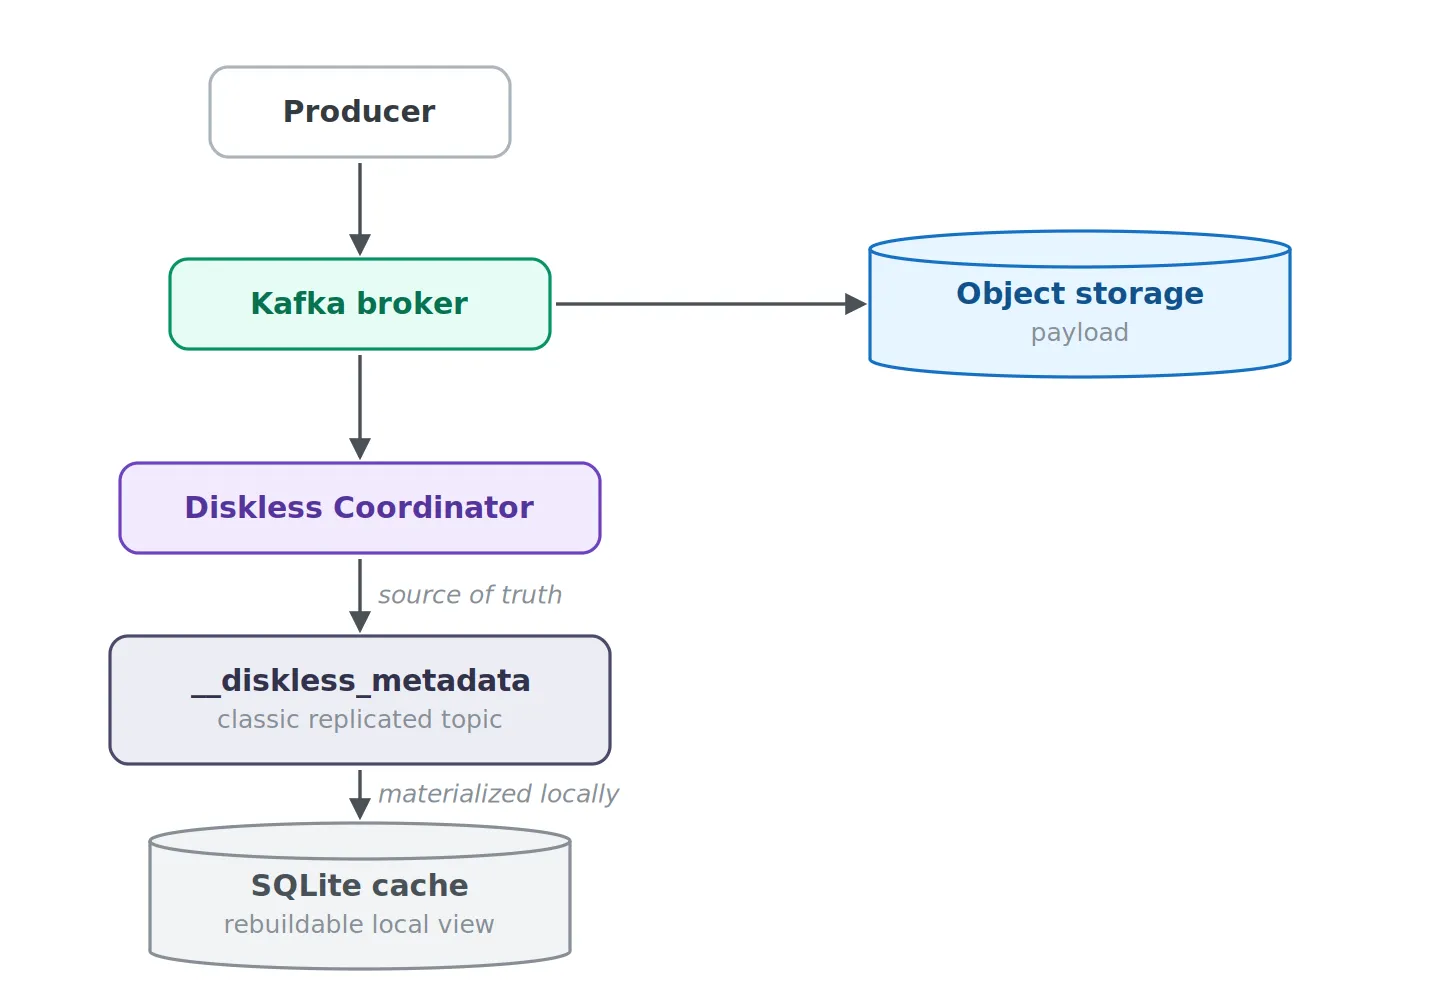
The diagram calls for one clarification, since it is easy to assume the opposite: __diskless_metadata is itself a classic Kafka topic, replicated across broker disks in the usual way – not a diskless topic. This is intentional for two reasons. A diskless topic relies on the coordinator, so the coordinator’s own storage must not rely on diskless topics. And keeping metadata on the classic replication path avoids an additional object-storage write during the commit; the producer still waits for the payload upload. The KIP’s risk analysis spells out the consequence: if the metadata topic loses too many in-sync replicas, diskless writes come to a halt. Object storage does play a part in the metadata story, but a supporting one – the proposal permits periodic snapshots of coordinator state to be kept in object storage, so the internal topic only needs to retain the deltas since the most recent snapshot.
Aiven’s production implementation currently chooses differently: its Batch Coordinator is built on PostgreSQL, whereas the upstream proposal relies on Kafka’s own internal topic as the source of truth and on SQLite as local materialized state. The specifics differ, but the direction is identical. Once payload storage is cheap and shared, the hard engineering shifts to metadata, ordering and recovery.
Reorganizing objects for reads
Cross-partition batching solves the write path but, unfortunately, hurts the read path. Say we ingest data into a newly written level-zero object like the one described earlier:
L0 object

P1 P7 P3 P18 P1 P9 P7 P2 P18 P1
For writes this is great – a single, reasonably large object-storage PUT carries data from many partitions. However, when a consumer wants to replay partition P7, the system might have to locate and range-read many separate objects simply to rebuild the sequential history of one partition. That is why diskless systems frequently introduce yet another database-like concept: background reorganization. Here the “level” in L0 earns its keep: in Redpanda, a background Reconciler rewrites those level-zero objects into bigger L1 files in which data is co-located and sorted by partition and offset. Conceptually:
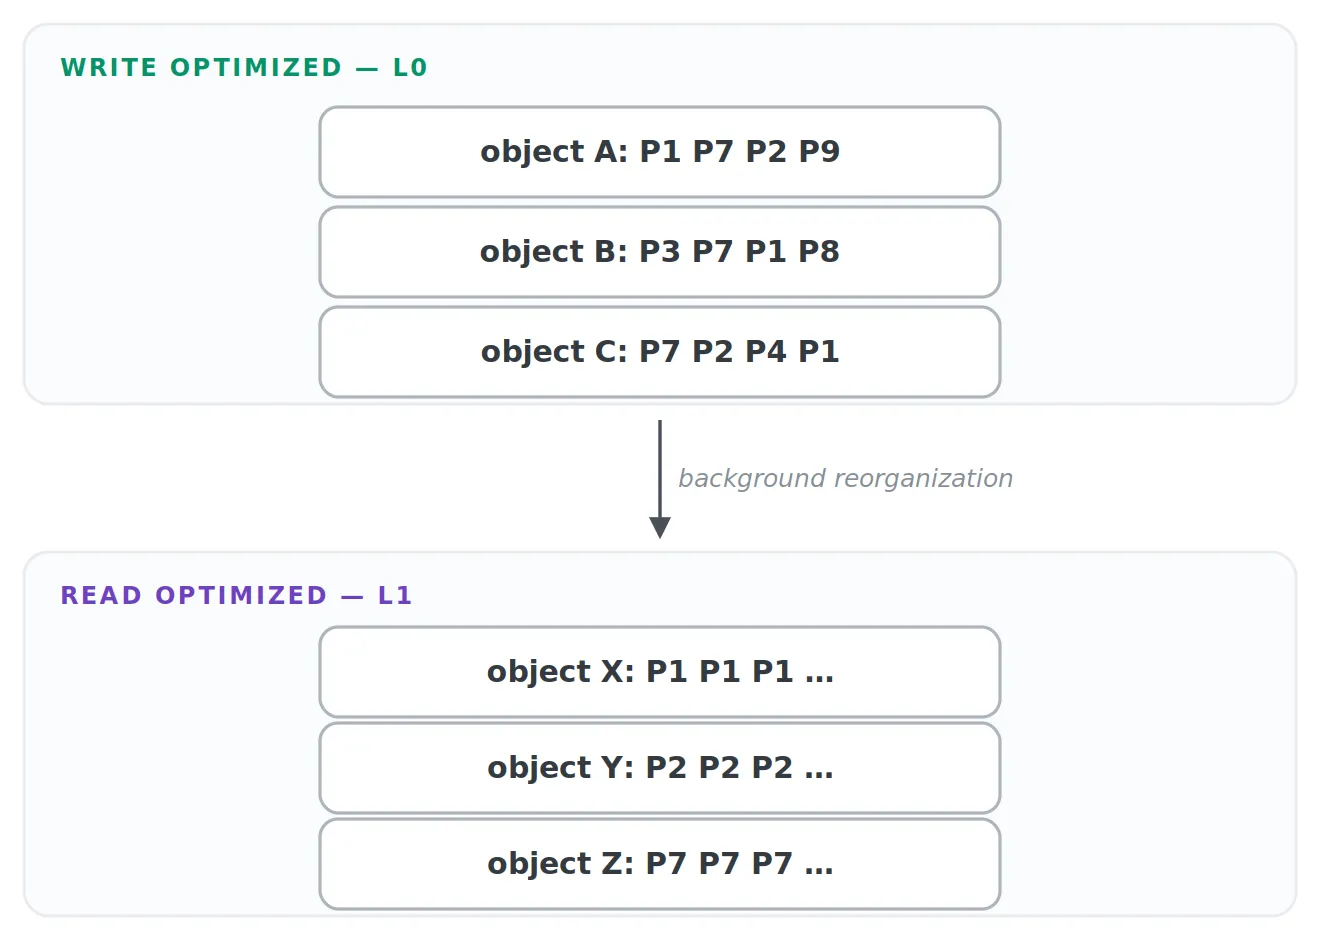
WarpStream runs background file compaction for much the same reason: recently ingested multi-partition files get reorganized to improve locality for historical reads. Kafka’s KIP-1163 contains a merging path, and the re-opened KIP-1165 investigates object compaction for the same class of problems.
Anyone who knows LSM trees will spot the pattern. Fast writes create one layout; efficient reads sooner or later call for another. A diskless streaming broker thus begins to resemble a purpose-built storage engine more than a directory of append-only log files.
Latency depends on the acknowledgement path
Placing object storage in the hot path comes with an obvious drawback: latency. A classic Kafka write can benefit from local storage and tightly controlled replication between brokers. A diskless implementation may have to gather enough records to form an efficient object, upload it, wait until the storage makes it durable, commit strongly consistent metadata, and only at that point acknowledge the producer. Make the batching window very short and you get many small objects and higher object-store request costs; make it long and latency goes up. This tension can’t be tuned away with configuration – it is inherent to the architecture.
Each system handles the trade-off in its own way. WarpStream defaults to a 250 ms batch timeout and can accept more object-store requests in return for lower latency; its current low-latency configurations rely on shorter timeouts and, on AWS, S3 Express. AutoMQ can place a faster WAL in front of object storage, so acknowledgement can hinge on the WAL rather than on the slower long-term path. Redpanda documents clearly higher end-to-end latency expectations for Cloud Topics running on public cloud object stores, and Confluent describes Freight in comparable terms. The current Kafka diskless proposal likewise states outright that remote storage will raise request and end-to-end latency compared to classic topics.
That is the architectural trade-off. Object storage brings elasticity and different economics at the price of a durability primitive with higher latency – or of adding a faster WAL in front of it.
What changes operationally
One of the arguments in favor of diskless architectures is that they make Kafka far simpler. From an operational standpoint, there is something to it: disk sizing, replica movement, rebalancing partition data, replacing disks, running out of broker storage and much of the cross-AZ payload replication either go away or matter less.
Distributed systems, however, seldom eliminate complexity – they shift it. Diskless systems must pay far more attention to object batching, metadata sequencing, object compaction, garbage collection, cache management, range-read efficiency, the economics of small objects, metadata recovery and tail-read behavior.
Classic Kafka invests a great deal of engineering effort in maintaining replicated physical logs. Diskless Kafka invests more of it in describing, caching and reorganizing data held in shared storage. The architecture is simpler along some operational dimensions, not across the board.
Does diskless Kafka actually make Kafka cheaper?
Typically, this is why the architecture exists at all. The biggest potential savings come from three places. First, less cross-AZ replication – the broker can write once to a regional object-storage service whose durability the cloud provider manages. Second, cheaper storage: per retained byte, object storage usually costs far less than large amounts of provisioned high-performance block storage. Third, compute is easier to scale: when brokers don’t own durable data, adding and removing compute nodes no longer means moving a proportional share of the retained dataset.
Yet “S3 is cheap” is not the whole cost model. You still pay for PUT requests, GET requests, range reads, metadata infrastructure, caches, background compaction, compute, and possibly high-performance WAL storage. That is why vendor claims of “Kafka that costs 90% less” need context: the architecture can certainly shift the economics for a high-throughput workload, but that doesn’t mean every Kafka bill will drop by 90%.
Where it fits
Diskless Kafka is particularly appealing for workloads that combine high throughput, long retention and a degree of latency tolerance: logs and observability streams, telemetry, CDC, clickstreams, data-lake ingestion, ML/AI ingestion and other large analytical event streams.
Such workloads move huge numbers of bytes and are often less concerned about a few hundred milliseconds – or even a full second – of extra latency than a service-to-service command path would be. Classic Kafka on local storage still makes a strong case for latency-sensitive event processing, commands, very hot tailing workloads and smaller retained datasets. That is why the probable end state is not one storage mode for all topics.
The future is probably multi-modal Kafka
This could be the most significant aspect of KIP-1150: diskless is proposed as a choice made per topic, not necessarily as an identity of the whole cluster. A future Kafka deployment might look like this:
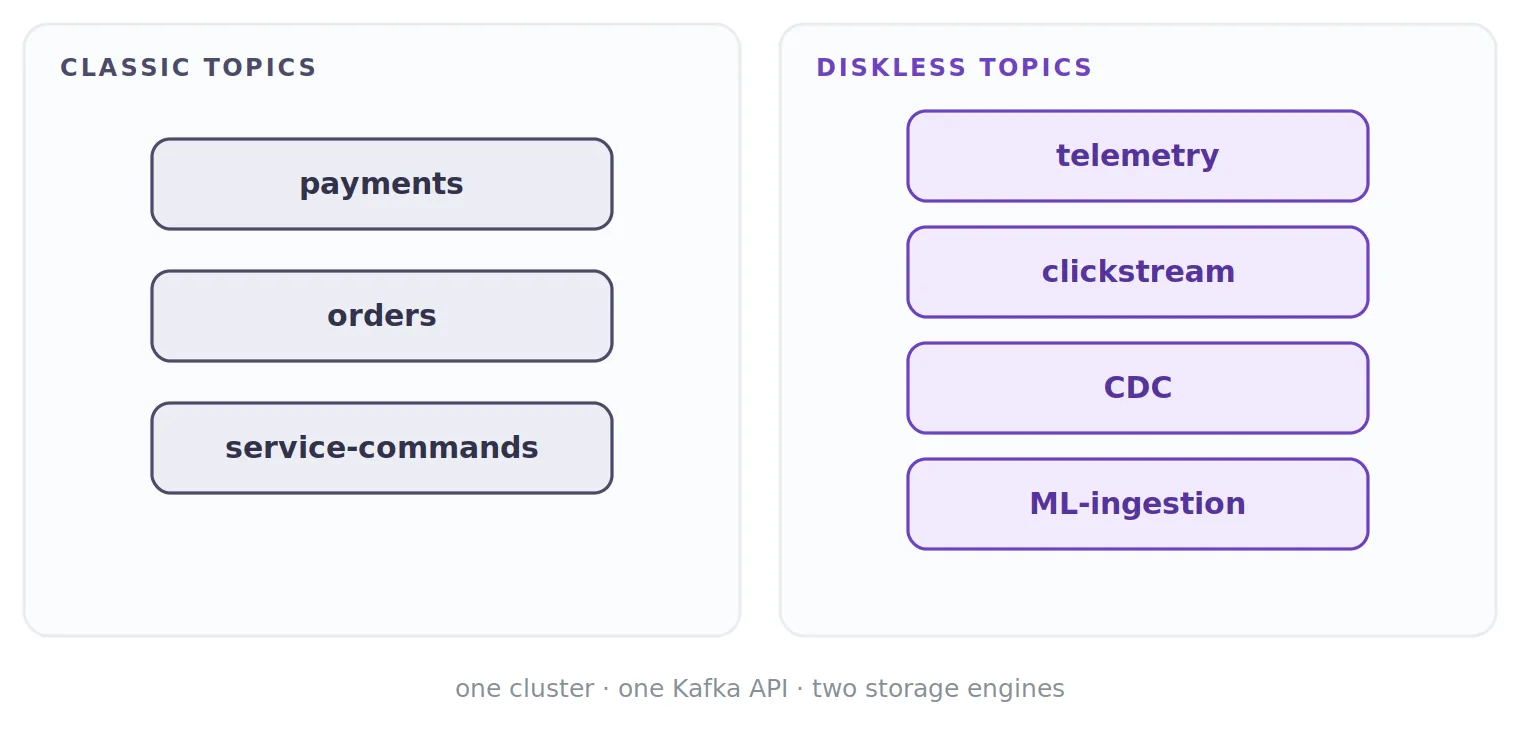
So one Kafka API and administrative boundary can conceal very different storage engines beneath it. Redpanda already supports local, tiered and cloud storage modes within a single engine. Aiven allows classic and diskless topics to coexist in one Standard Kafka service; its current feature limits still rule out transactions, compacted diskless topics and Kafka Streams state stores. A one-way conversion from classic to diskless is also available in early availability. Upstream Kafka’s KIP-1163 explicitly foresees classic, tiered and diskless topics sharing a cluster, letting applications make the cost/latency trade-off per topic instead of per platform.
That is a more intriguing future than just wondering whether “diskless Kafka will take Kafka’s place.” Kafka itself may turn multi-modal.
The Kafka protocol may outlive Kafka’s original architecture
Kafka’s API has outgrown Kafka’s original storage design. Applications work with topics, partitions, offsets, producers, consumers, consumer groups, transactions, and Kafka protocol semantics. They don’t necessarily care whether the underlying bytes are stored in:
ext4
XFS
NVMe
EBS
S3
GCS
Azure Blob
This is what has let WarpStream, AutoMQ, Redpanda, and others stay Kafka-compatible while experimenting boldly beneath the protocol boundary – and now Apache Kafka itself is beginning to head the same way. Kafka was designed on the premise that sequential disk I/O could make a persistent distributed log extremely fast. That premise was right, and diskless Kafka doesn’t disprove it. The newer question is whether running Kafka in the cloud still requires the broker to own the durable log in the first place.
The answer is giving rise to architectures that resemble modern cloud databases more than the Kafka clusters of the 2010s:
stateless-ish compute
       +
shared object storage
       +
strongly consistent metadata
       +
caching
       +
background compaction
So, is diskless Kafka the future?
Not for all topics. For high-throughput streaming in the cloud, however, the trend is difficult to dismiss.
The traditional Kafka architecture still offers excellent properties for latency-sensitive workloads. Local sequential storage is fast, and a tightly integrated leader with a replicated log is still a simple yet powerful abstraction. The systems discussed here already provide a number of diskless designs. For a real deployment, what is worth comparing is acknowledgement latency, recovery behaviour, feature support and total cost for the given workload.