Start with a Log or with a Table? Apache Kafka, Fluss, and Streaming Tables
Comparing, at the architecture level, log-first streaming systems (Apache Kafka) with table-first storage abstractions (Apache Fluss), looking at CDC workloads, duplicated state, and integration with the lakehouse.
For a streaming architecture, Apache Kafka is the obvious place to begin. Applications publish events to Kafka, other applications read them, and data that has to be kept longer ends up in object storage sooner or later. A pretty common setup relies on Kafka Connect with an S3 sink connector – such as Confluent’s Amazon S3 Sink Connector – to offload older data to Amazon S3:
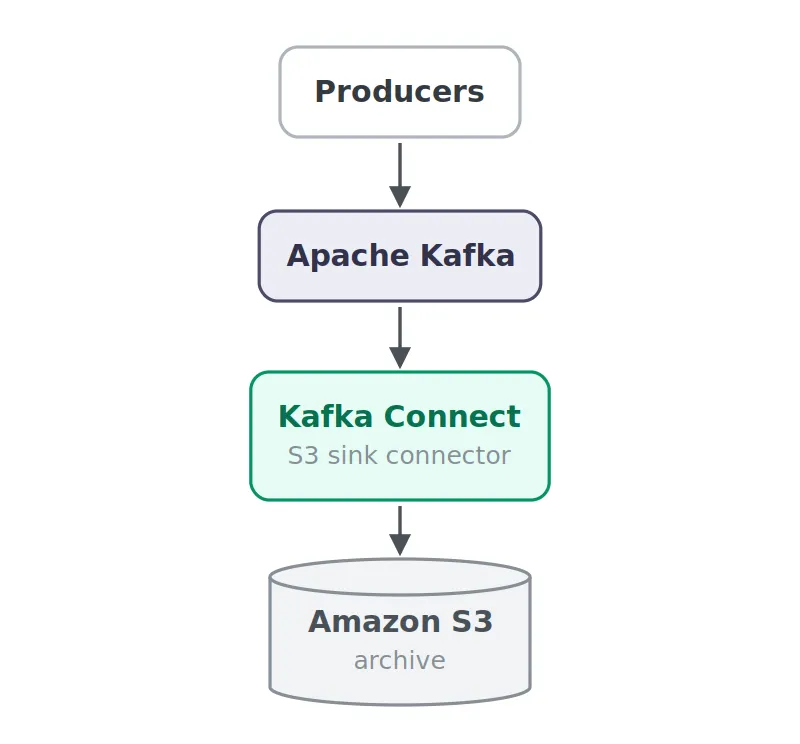
Kafka takes care of the real-time path, S3 offers inexpensive, durable storage for historical data, and for archival purposes that’s frequently sufficient. Trouble begins once the data in S3 is supposed to act less like an archive and more like a database table.
Imagine a Kafka topic holding customer updates:
customer-123 -> { name: "Alice", status: "active" }
customer-456 -> { name: "Bob",   status: "active" }
customer-123 -> { name: "Alice", status: "blocked" }
Dumping these records into Parquet is simple. A different set of questions is much tougher to answer:
- What does each customer look like right now?
- How do we represent updates and deletes?
- Which files make up a consistent version of the dataset?
- What happens when the schema evolves?
- How do we keep from generating thousands of tiny files?
- How can several query engines read the same dataset safely while it’s being updated?
S3 hands us files. A table is something it doesn’t provide.
From files to tables
This gap is filled by open table formats like Apache Iceberg and Apache Paimon. They wrap the files in metadata: schema, snapshots, partitions, data files, and the changes from one version to the next. The architecture then looks more like this:
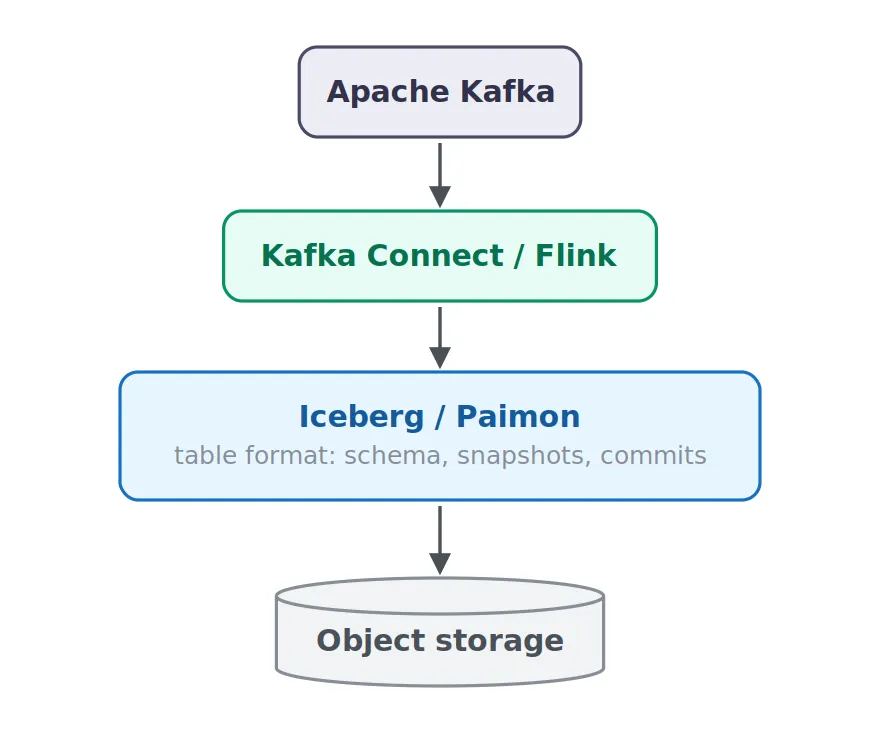
What changes goes beyond how files are laid out. We’re no longer just writing files – we’re maintaining a table. Queries can run against a consistent snapshot, schema changes can be tracked, and data files can be compacted or swapped out without readers ever seeing a half-updated state.
Still, someone has to turn the Kafka stream into that table. In practice, that means operating yet another piece of infrastructure: Kafka Connect, Apache Flink, Spark Structured Streaming, AWS Glue, or a custom ingestion service. And this service has a lot more on its plate than shuffling bytes from Kafka to S3. It may have to understand schemas, convert CDC records into inserts, updates, and deletes, produce table commits, control file sizes, compact small files, and register metadata in a catalog.
There are two noteworthy approaches to simplifying this pipeline. Confluent’s Tableflow turns Kafka-to-lakehouse materialization into a managed Confluent Cloud feature; we’ll return to it later. Apache Fluss goes a different way and asks whether the streaming layer ought to be a log at all. Before we get to Fluss, it’s worth spelling out exactly what Kafka offers.
Kafka remains a log
A Kafka partition is an ordered log. Each record has an offset, producers append records, and consumers advance through the log and can rewind to replay older data.
This model is intentionally simple. Kafka doesn’t need to know whether a record stands for a customer, an invoice, a database row, or an HTTP request – to the broker, the record’s value is largely an opaque byte sequence. That’s one of Kafka’s strengths and the reason it works so well as a general-purpose event backbone. But it also means Kafka’s storage abstraction is, at its core, a log.
Take a compacted topic:
offset 100: customer-123 -> active
offset 101: customer-456 -> active
offset 102: customer-123 -> blocked
At some point, log compaction may drop the older value for customer-123 and keep the newer one. This makes a compacted topic resemble a key-value store, but only when viewed from afar. Kafka holds enough information to rebuild the latest state; it doesn’t expose that state as a table. No broker operation corresponds to:
SELECT *
FROM customers
WHERE customer_id = 'customer-123';
A consumer can read through the log and construct such a representation, but that representation resides elsewhere. Kafka Streams builds local state stores - and ksqlDB, which sits on top of Kafka Streams, offers precisely this pattern as SQL tables that are continuously materialized from topics. Flink keeps operator state, typically backed by RocksDB. Applications also materialize Kafka data into Redis, Cassandra, PostgreSQL, Elasticsearch, or some other database.
In Kafka-based projects, I run into variations of the same picture again and again: a customer or product dataset kept as Flink state for enrichment joins, duplicated in Redis so services can query it with low latency, and written to the lakehouse for analytics. Every copy has a justifiable reason to exist. Taken together, though, that’s three or four stateful systems holding one and the same logical table:
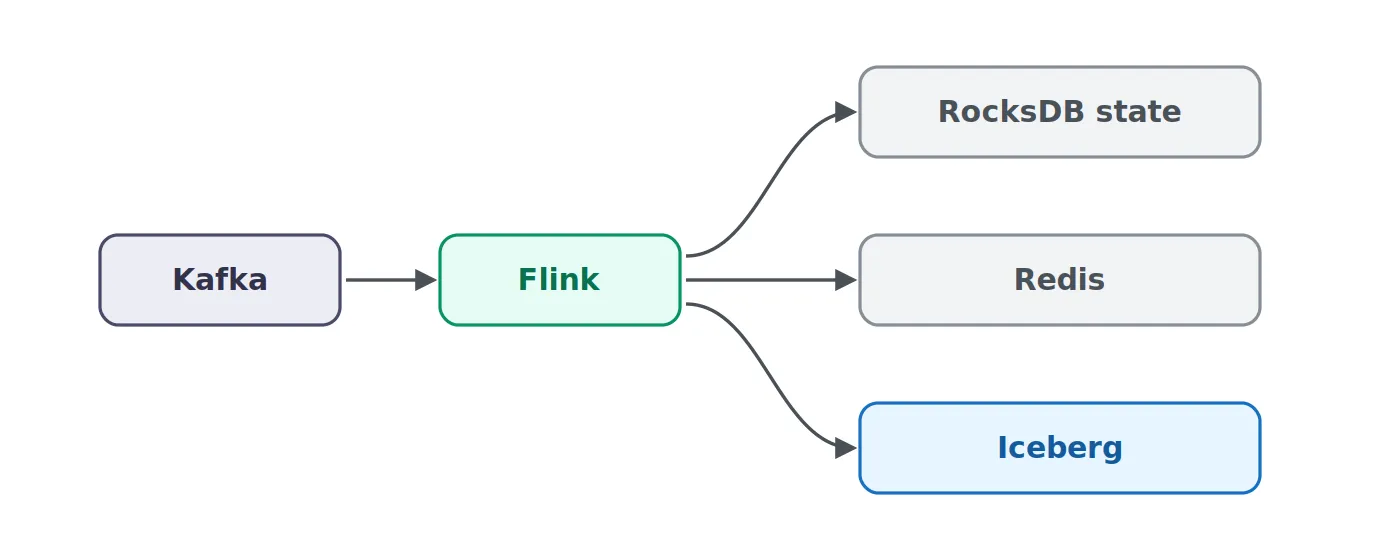
Kafka keeps the changelog, a state store serves the most recent value, and the lakehouse keeps historical data for analytical queries. Splitting these responsibilities has its merits, but it also means an apparently simple stream of updates gets copied into several stateful systems – each with its own story around consistency, capacity, and operations.
Fluss targets precisely this duplication.
Fluss begins with a table
First, a bit of background on the project, since it’s young. Fluss was born at Alibaba, joined the Apache Incubator in 2025, and became an Apache Top-Level Project in August 2026. At the time of writing, the newest stable release is 0.9.1; its artifact still has the Incubating label, as the release came out before graduation. Flink is still the most complete compute integration, but Fluss now also provides Java, Rust, Python, and C++ clients – the non-Java ones are built on a shared Rust core and saw their first 0.1.0 release in 2026, so feature coverage still differs between languages. The ecosystem is young, and any adoption decision should take that into account.
Fluss handles append-only streams, but that isn’t what sets it apart from Kafka. The more interesting abstraction is the Primary Key Table. A Fluss table can be declared with a key:
CREATE TABLE customers (
    customer_id STRING,
    name STRING,
    status STRING,
    PRIMARY KEY (customer_id) NOT ENFORCED
);
Let’s look again at the same series of updates:
customer-123 -> Alice, active
customer-456 -> Bob, active
customer-123 -> Alice, blocked
The table’s current state is:
customer-123 -> Alice, blocked
customer-456 -> Bob, active
Meanwhile, downstream streaming consumers can still see the changes. That’s the crucial difference. In Kafka, the log is the main storage abstraction, and current state is usually derived from it. In a Fluss Primary Key Table, both the changelog and the current state belong to the storage abstraction.
Under the hood, Fluss doesn’t make the state problem vanish. Primary Key Tables keep both a log component and a key-value component, using RocksDB for current state:
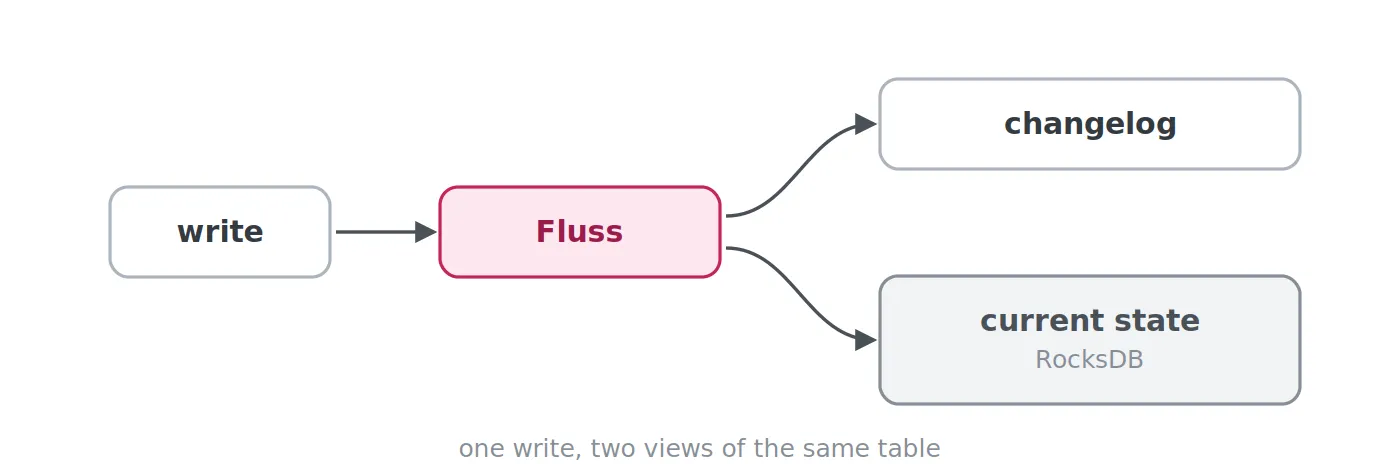
So Fluss doesn’t get rid of RocksDB – it shifts the ownership of it. Rather than each processing application separately keeping its own copy of the same state, the storage layer keeps it once and makes it available to many consumers. For CDC datasets, lookup joins, and widely reused reference data, this can eliminate a surprising amount of duplicated state.
A compacted log isn’t a primary-key table
Kafka compaction and a primary-key table may seem alike, since both handle multiple values tied to the same key, yet they address different questions. Kafka compaction mainly addresses:
Is it possible to keep a replayable log without holding on to every historical value of every key forever?
A primary-key table addresses:
What value does this key have at the moment?
These requirements are related, but they result in different storage designs. Kafka stays optimized for ordered consumption; a primary-key table additionally needs efficient access to state.
Kafka Streams illustrates the difference nicely. A Streams application can read a compacted topic and keep a local RocksDB store: Kafka supplies the durable changelog, and RocksDB supplies efficient access to the materialized state. Fluss pulls that materialization into the storage system itself.
Whether this helps depends on the workload. For processing state specific to one application, local state may be exactly the right thing – a Kafka Streams application might hold state that exists solely because of its processing logic, and moving it into a shared database would hardly make sense. But picture a large customer or product dataset read by ten different Flink jobs. If each job needs the same latest state for lookup joins, rebuilding and maintaining ten copies of it is far less clearly a good idea, and a shared streaming table begins to look appealing.
The hot layer can be columnar too
There’s another difference that’s easy to overlook: by design, Kafka has no understanding of a message value’s structure. Say an event has fifty columns:
customer_id
name
email
address
country
currency
segment
device
browser
...
A Flink job may only need customer_id and country. With Kafka, the consumer still pulls records carrying the entire serialized value, and columns are selected only once the record has reached the consumer and been deserialized.
Fluss works differently. Its log representation can rely on Apache Arrow, so the storage layer is aware of columns. A query like:
SELECT customer_id, country
FROM customers;
can have its projection pushed down into the storage layer, so that only the needed columns are sent over the network. We usually think of column pruning in the context of Parquet files in a data lake, not a system serving fresh streaming data – here, the hot streaming path starts to resemble an analytical storage engine somewhat. And the columnar layout pays off beyond data transfer: values of one column are stored next to each other in memory, which is precisely the layout aggregation thrives on – summing a numeric column across Arrow batches is a very different operation from extracting a single field from every separately deserialized record. Once again, this follows from the underlying abstraction.
Kafka sees records. Fluss sees rows.
For history, the lakehouse still wins
Being able to query the hot layer doesn’t mean it should hold years’ worth of data. Object storage is still far cheaper, and analytical systems excel at scanning large columnar datasets stored there. That’s why Fluss supports tiering older data into lakehouse tables like Paimon or Iceberg:
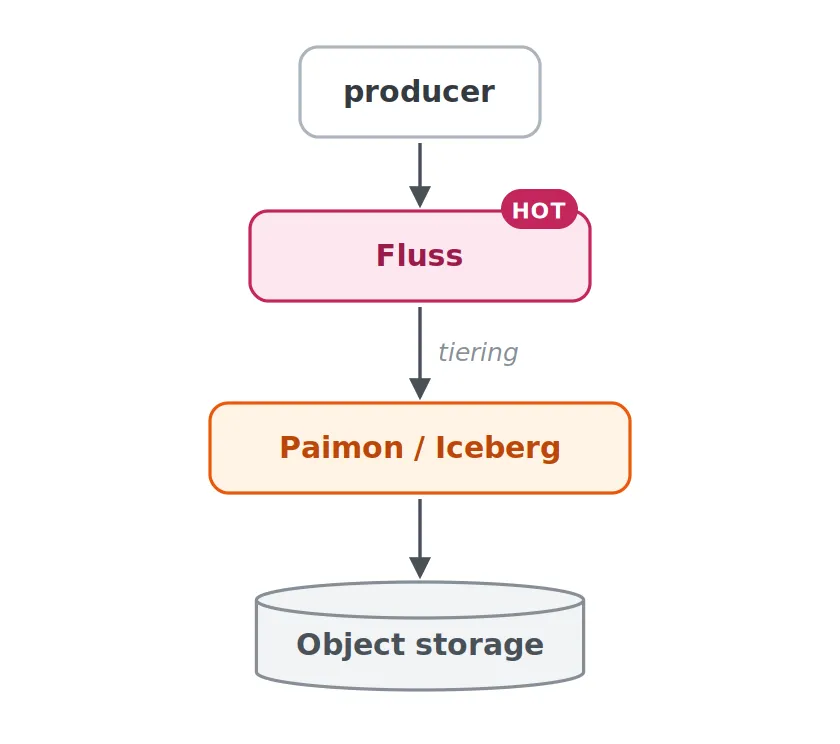
The same logical table now stretches across two storage tiers: Fluss serves the hot portion, and the lakehouse keeps the history. The tricky part is running queries across that boundary.
Let’s say the lakehouse holds everything committed up to 12:00:00, while thirty seconds of newer data are still only in Fluss. At 12:00:30, a query against the lake alone returns a stale result. Making every single event instantly visible in Iceberg or Paimon isn’t the solution either – lakehouse formats work with files and snapshots, and very frequent commits produce precisely the small-file and metadata issues these systems exist to keep in check. For update-heavy streams, the trade-off becomes even sharper: with copy-on-write, each commit rewrites data files, so writes bear the cost; with merge-on-read, writes remain cheap, but readers have to merge the growing pile of delete files until compaction catches up – so fast reads require frequent compaction of the table. Raise the commit frequency far enough and one side or the other has to give.
Fluss addresses this by combining the stable historical snapshot with the hot tail:
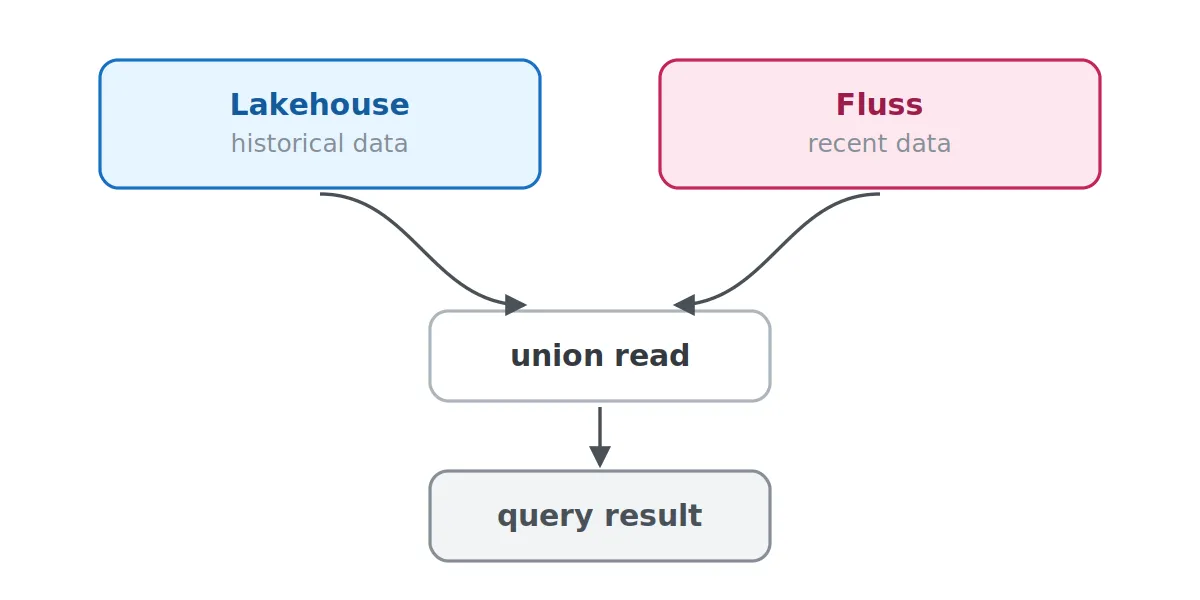
The full logical table doesn’t have to be physically kept in one location. Older data can sit cheaply in object storage, while fresh data stays in low-latency streaming storage.Consider how this affects the Iceberg trade-off described above: the union read doesn’t make copy-on-write or merge-on-read any cheaper, but it eliminates the need to run them at streaming frequency at all – the lakehouse can commit and compact at whatever pace keeps the table in good shape, since freshness comes from Fluss instead of being wrung out of Iceberg.
Fluss isn’t the only system with this hot/cold split. Confluent Cloud now provides a similar path built on Kafka.
What’s different on Confluent Cloud: Tableflow
Confluent Tableflow is how Confluent tackles the Kafka-to-lakehouse pipeline. The key caveat: Tableflow is a Confluent Cloud service. It isn’t part of Apache Kafka, nor is it available in self-managed Confluent Platform. Everything in this section therefore describes a managed Confluent Cloud architecture, not a new storage primitive within Kafka itself.
Within those limits, Tableflow can continuously materialize a Kafka topic into an Iceberg or Delta Lake table:
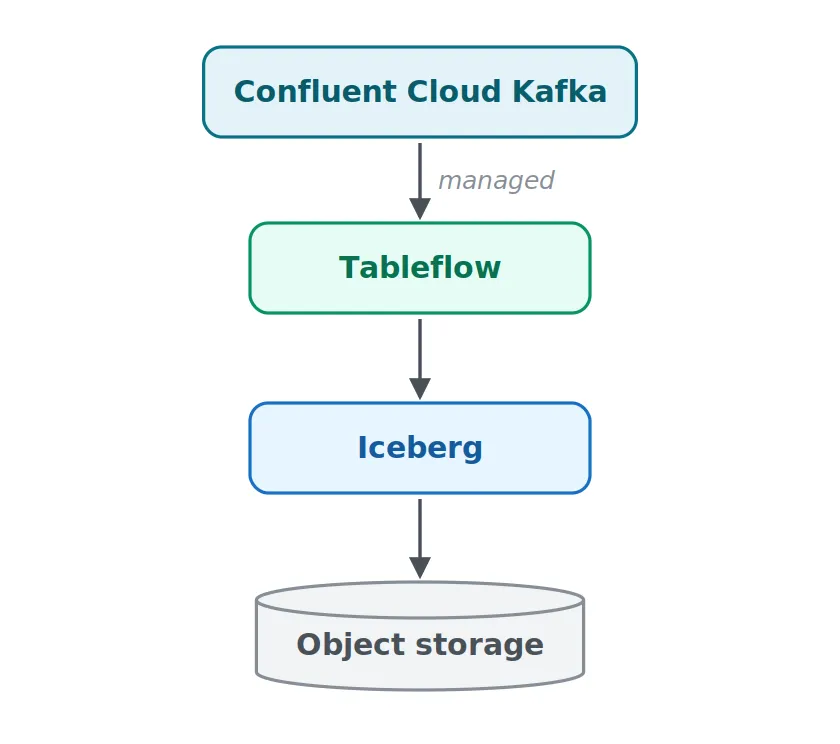
The pipeline that used to need Connect, Flink, or custom application code becomes a part of the platform. For append-only topics, the mapping is fairly simple: records become rows and are written into the table. More interestingly, Tableflow also offers upsert-style materialization for compacted topics, so a stream of changes can turn into a table that reflects current state.
The resulting hot/cold split looks strikingly like the Fluss tiering diagram. Kafka holds the fresh events, Iceberg holds the materialized historical table, and Confluent’s Flink integration can merge a Tableflow snapshot with records that haven’t made it into the materialized table yet:
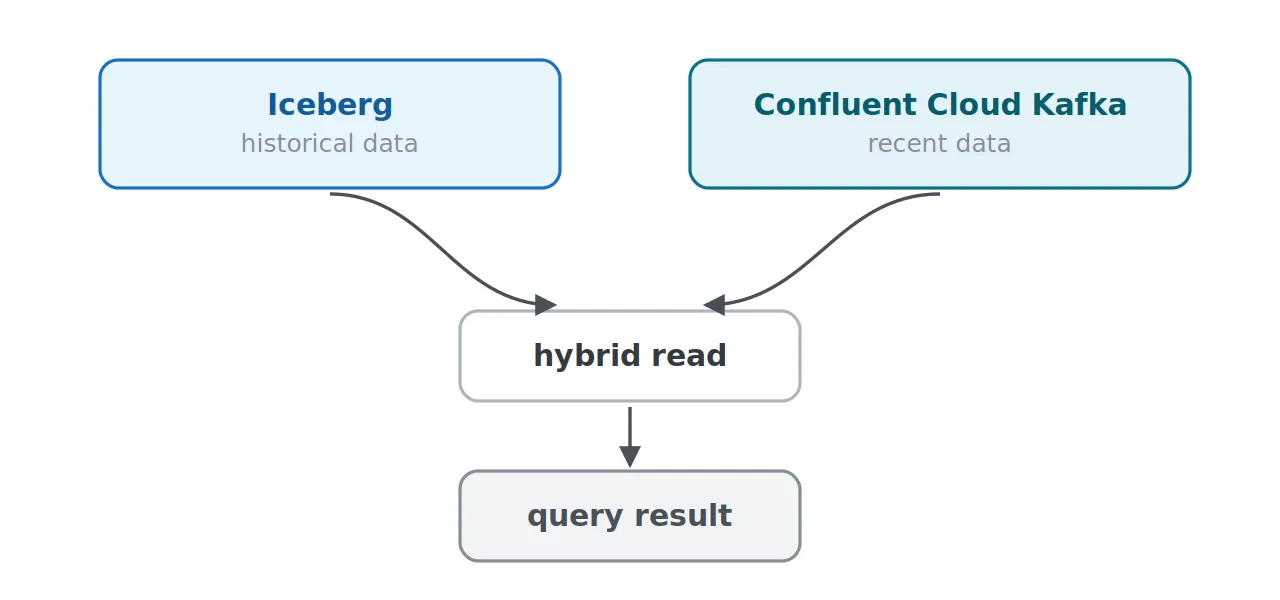
The semantics and implementation are not the same as Fluss union reads, but the underlying trick is identical: don’t make the lakehouse deliver millisecond freshness. Read the stable portion from the lake and the tail from the streaming system. Even though the two stacks start from different abstractions, they arrive at a similar hot/cold layout.
Tableflow significantly narrows the gap in the Kafka-versus-Fluss comparison. With self-managed Apache Kafka, turning a topic into a maintained lakehouse table typically means running yet another pipeline. On Confluent Cloud, Tableflow takes away most of that plumbing. What’s left is the difference in the hot layer. If applications additionally need low-latency access to current state, the architecture still requires another branch, whereas with Fluss that state can live in the storage layer:
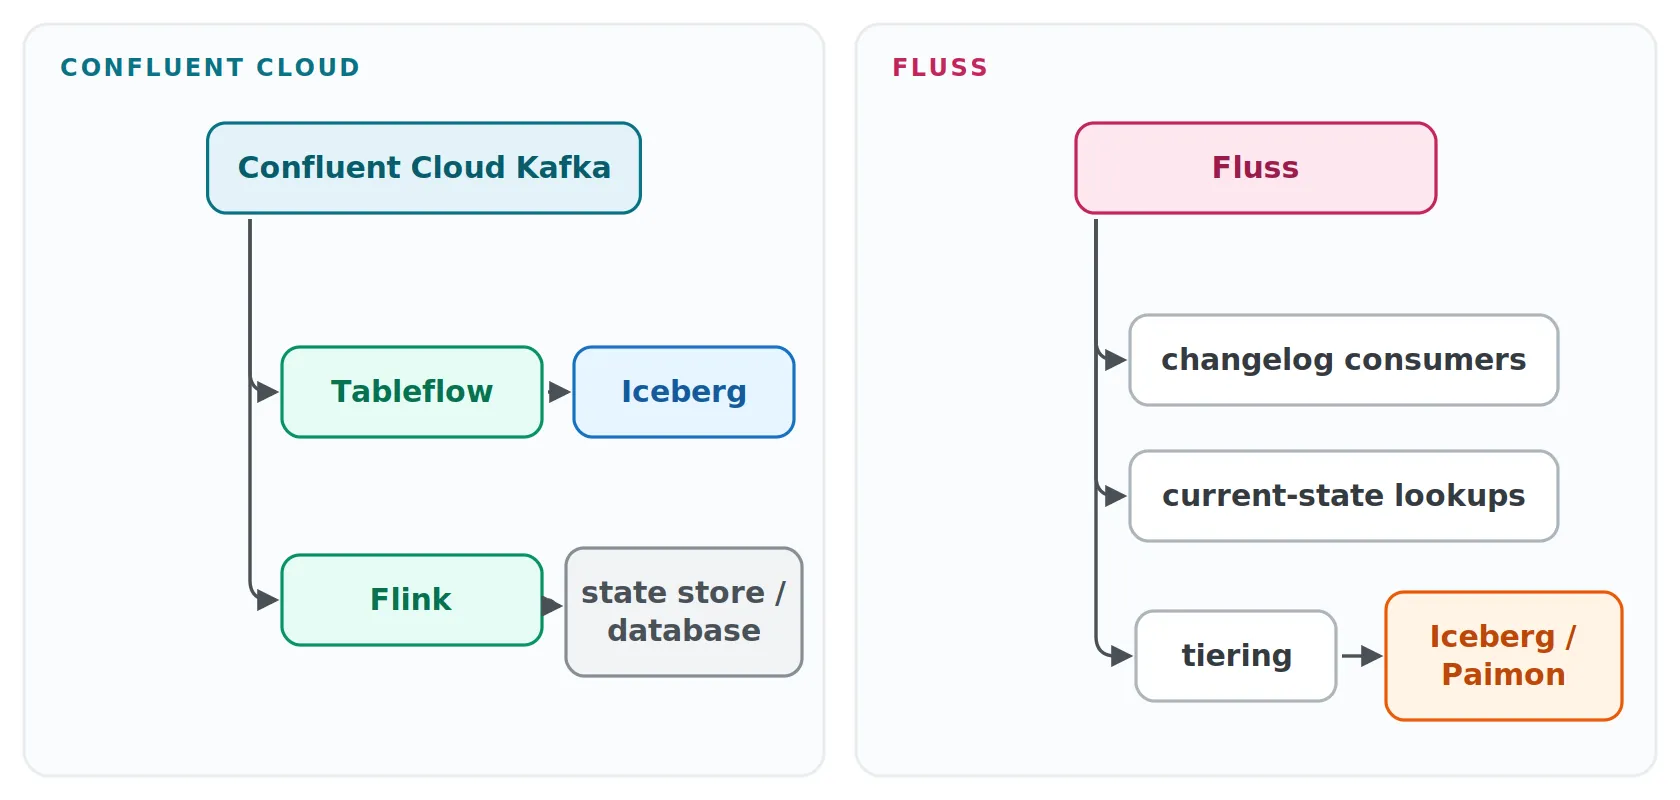
This leaves us with a more valuable question than “can Fluss get streaming data into Iceberg more efficiently than Kafka?”: do we still need a separate materialization of current state if the streaming storage can expose it directly?
Kafka semantics still seep into the table
Tableflow’s upsert mode also reveals what happens when a table is derived from a log. Kafka guarantees ordering and compaction per partition, so the partitioning model unavoidably becomes part of the resulting table’s semantics.
Say a key is first mapped to one partition:
partition 3:
customer-123 -> active
Later, once the topic’s partition count has changed, that same key may land somewhere else:
partition 8:
customer-123 -> blocked
In business terms, it’s still a single customer. Kafka sees two separate partition histories. Repartitioning is one of those edge cases where the underlying abstraction abruptly shows through: a table derived from a log isn’t quite the same as a storage system whose data model is a table.
Where does Paimon come in?
Paimon fits a bit awkwardly into a title like “Kafka vs Fluss vs Paimon”, since it addresses a different layer of the problem. Fluss can use Paimon for its lakehouse storage, but Iceberg works as well. So there are actually two independent choices: the hot layer (Kafka or Fluss?) and the lakehouse representation (Iceberg or Paimon?).
Paimon began within the Flink community as Flink Table Store before it became a top-level Apache project, and this heritage is visible in its design. Internally, every bucket of a Paimon table is structured as an LSM tree – a structure designed to absorb continuous writes and updates rather than occasional batch appends. Its primary key tables offer configurable merge engines that determine what happens when several records arrive for one key: deduplicate keeps the newest row, partial-update lets separate writers populate different columns of a single row, and aggregation combines incoming values into aggregates. Paimon can also emit a proper changelog for downstream streaming readers, with several changelog-producer modes that balance write cost against changelog completeness.
Paimon is designed on the assumption that “a stream of changes to a table” is an ordinary workload, not an edge case. This makes it a natural match for CDC-heavy pipelines and helps explain why it works so well together with Fluss, which emerged from the same Flink ecosystem.
Iceberg comes from a somewhat different angle and brings a big advantage of its own: ecosystem adoption. Analytical engines and cloud data platforms support it broadly, which makes it a natural interoperability layer. As a result, Fluss + Iceberg can be an entirely sensible architecture too. What defines Fluss isn’t the use of Paimon – it’s the streaming table in the hot layer.
Kafka Tiered Storage addresses a different problem
Kafka also supports Tiered Storage on its own, which can muddy the terminology. If Kafka can offload old log segments to object storage, why go to the trouble of converting the data into Iceberg or Paimon? Because what you end up with is different.
The remote files remain part of the Kafka log. Kafka consumers can read them using Kafka semantics, but they don’t turn into a table that Spark, Trino, or another engine can query on its own as Iceberg. Tableflow and Fluss lakehouse tiering do something different:
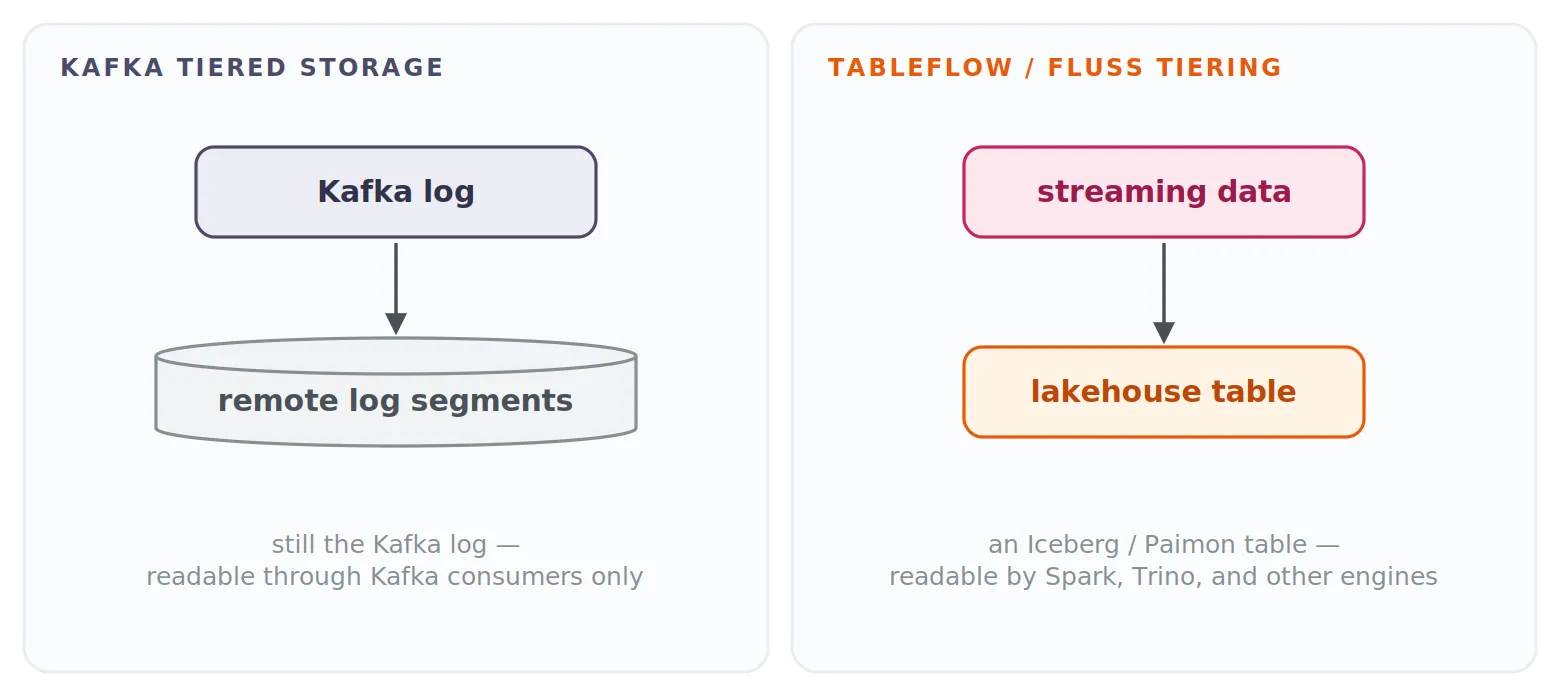
Both rely on object storage. Only one of them changes how the data is represented.
Is Fluss a replacement for Kafka?
Not in the usual sense of the word. Kafka is far more than a storage engine. A production Kafka deployment comes with client libraries, Kafka Connect connectors, Schema Registry integrations, Kafka Streams applications, monitoring, operational tooling, managed services, and years of accumulated engineering know-how. Many architectures also rely on Kafka as an organization-wide integration backbone, and for that kind of workload, replacing Kafka isn’t about whether some other system can append and replicate records – the surrounding ecosystem counts at least as much.
Nor is Fluss a Kafka-compatible broker that you can slot in beneath existing producers and consumers. Kafka protocol compatibility was debated in the Fluss community and was dropped from the project roadmap; one argument was that the Kafka protocol would expose only part of what Fluss tables are capable of. That decision reveals a lot about where the project is heading. Fluss isn’t aiming to be a faster Kafka with a different storage engine.
That said, a drop-in replacement may not be the migration worth thinking about anyway. Consider a system that has gradually grown into:
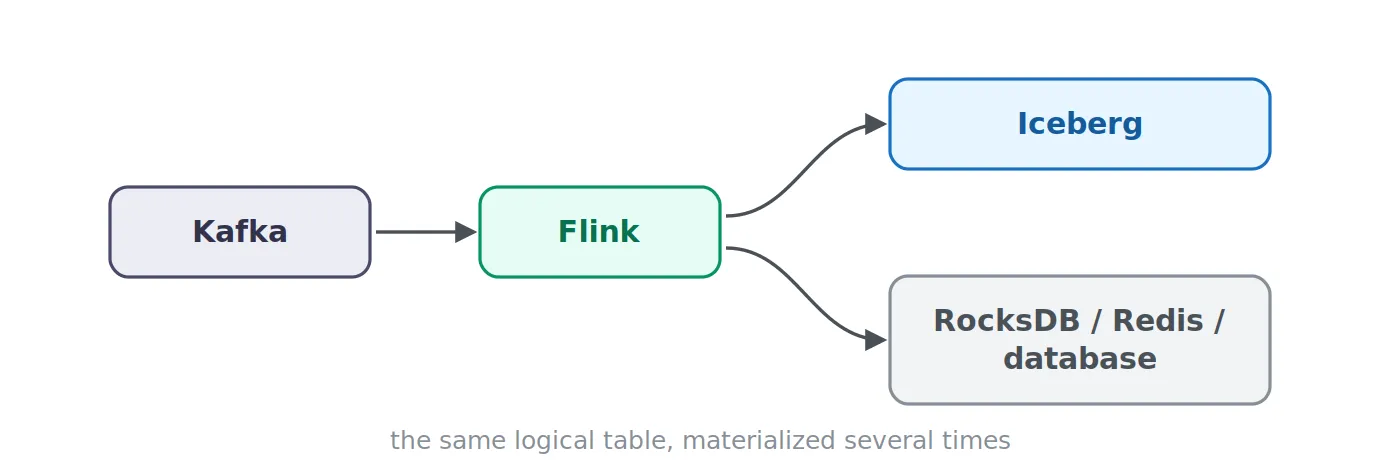
Each component in that diagram may well be justified. The RocksDB state may be specific to the application; Redis may serve a different latency or availability target; Iceberg is there for analytics. Sometimes, though, the copies exist for a more fundamental reason: the streaming system exposes a log, whereas the consumers need a table. That’s the scenario Fluss is built for.
Log first, or table first?
Kafka turned the distributed log into the standard foundation for modern streaming systems, and that model is exceptionally good at moving immutable facts between independent consumers. At the same time, a growing share of streaming workloads are in fact streams of changes to tables. CDC is the textbook case: the INSERT customer, UPDATE customer, DELETE customer events are valuable as a log, but what many consumers really want in the end is the customers table – the current state available right away, and older versions available when required.
The lakehouse ecosystem has already pushed historical storage that way. Iceberg and Paimon turn object storage into tables; on Confluent Cloud, Tableflow can derive such a table straight from Kafka. Fluss poses the same question one layer earlier: why should hot storage still expose nothing but a log?
This gives us two distinct starting points: a log-first architecture and a table-first streaming architecture:
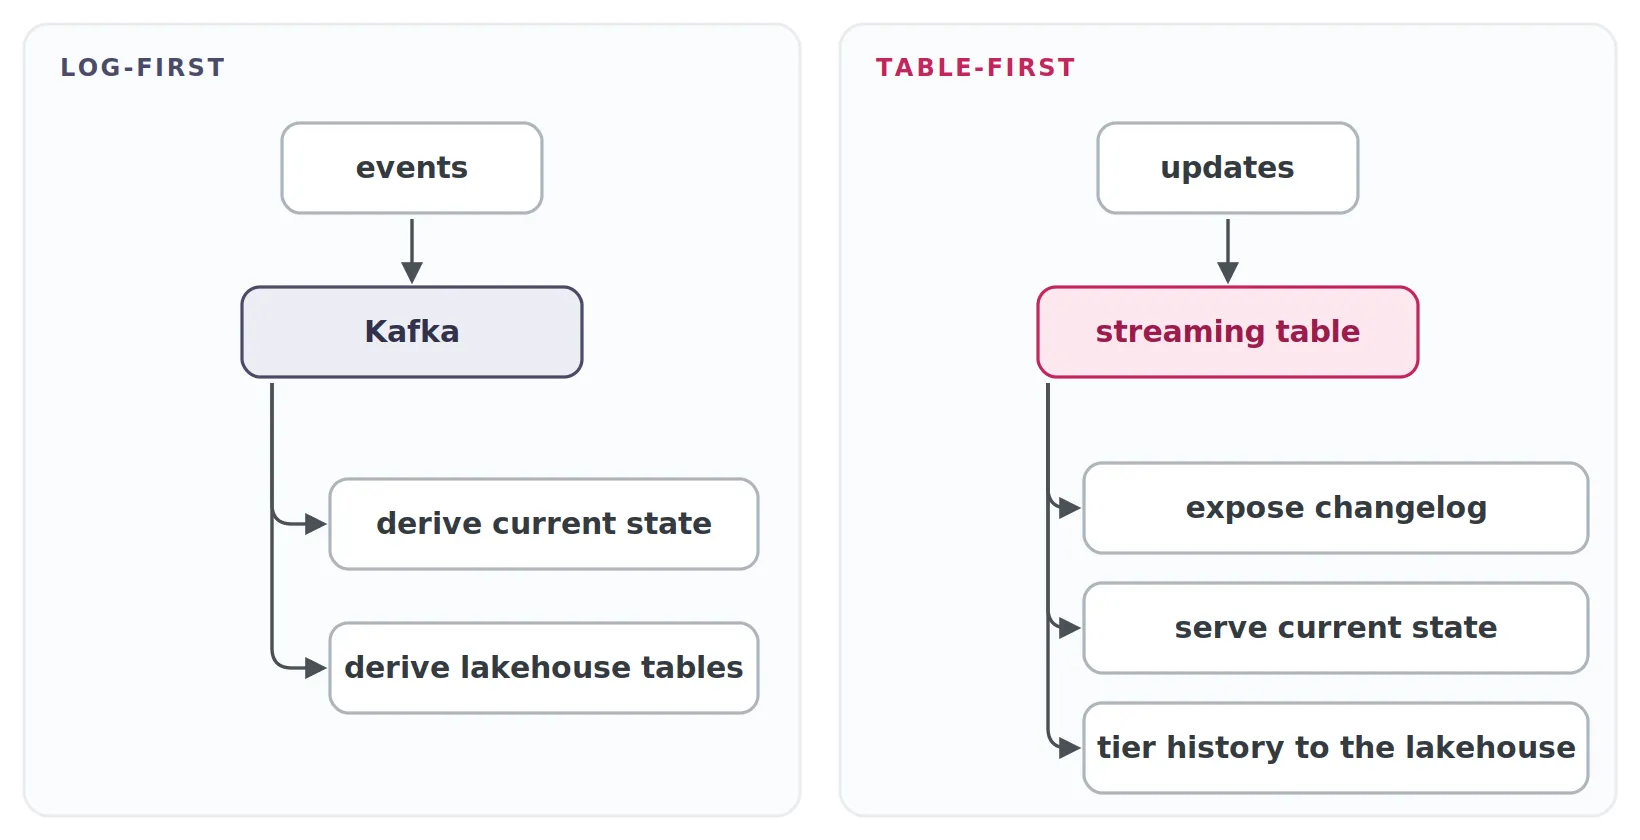
I don’t expect streaming tables to render Kafka obsolete. A more likely result is that they shrink the set of workloads for which a log must serve as the primary storage abstraction. And that makes the interesting question far less dramatic than “Will Fluss replace Kafka?” – and far more useful:
If the data we stream is, in the end, a table, should we begin with the log and rebuild the table afterwards, or store the streaming table from the outset?