Kafka Was Born at LinkedIn. What Did LinkedIn Change Once Kafka Stopped Being Enough?
A look at LinkedIn's Northguard and Xinfra systems and at how they rework Kafka-style log storage, replication, and metadata to overcome scaling limits tied to partitions.
Kafka was created at LinkedIn around 2010 as a way for services to publish data, consume it independently, and replay it whenever needed. By 2025, LinkedIn said it was processing over 32 trillion records and 17 PB every day, spread across 400,000 topics, more than 10,000 machines, and about 150 clusters.
Running infrastructure of that size called for a growing collection of services handling balancing, recovery, and cluster management. LinkedIn answered with Northguard, a new log storage system, and Xinfra, a virtualization layer allowing applications to work with both Kafka and Northguard.
Northguard retains producers, consumers, ordered logs, replication, and replay. What changes lies beneath the surface: smaller units of replication, a sharded control plane, and topics able to move between storage systems.
About the sources: This article looks at the design and deployment report LinkedIn published in June 2025. At that point, Northguard and Xinfra were internal, closed-source systems; LinkedIn told InfoQ that it might open source them at a later date. While writing this article, I couldn’t find any public release. As a result, the claims about performance and reliability come from LinkedIn itself, with no public implementation available for independent inspection or benchmarking. How they hold up on other workloads, hardware, and Kafka configurations hasn’t been verified.
Kafka partitions carry many responsibilities
A Kafka partition is an ordered log, yet it also governs replication, broker placement, and the way consumers split up the work. Multiple responsibilities share one and the same boundary:
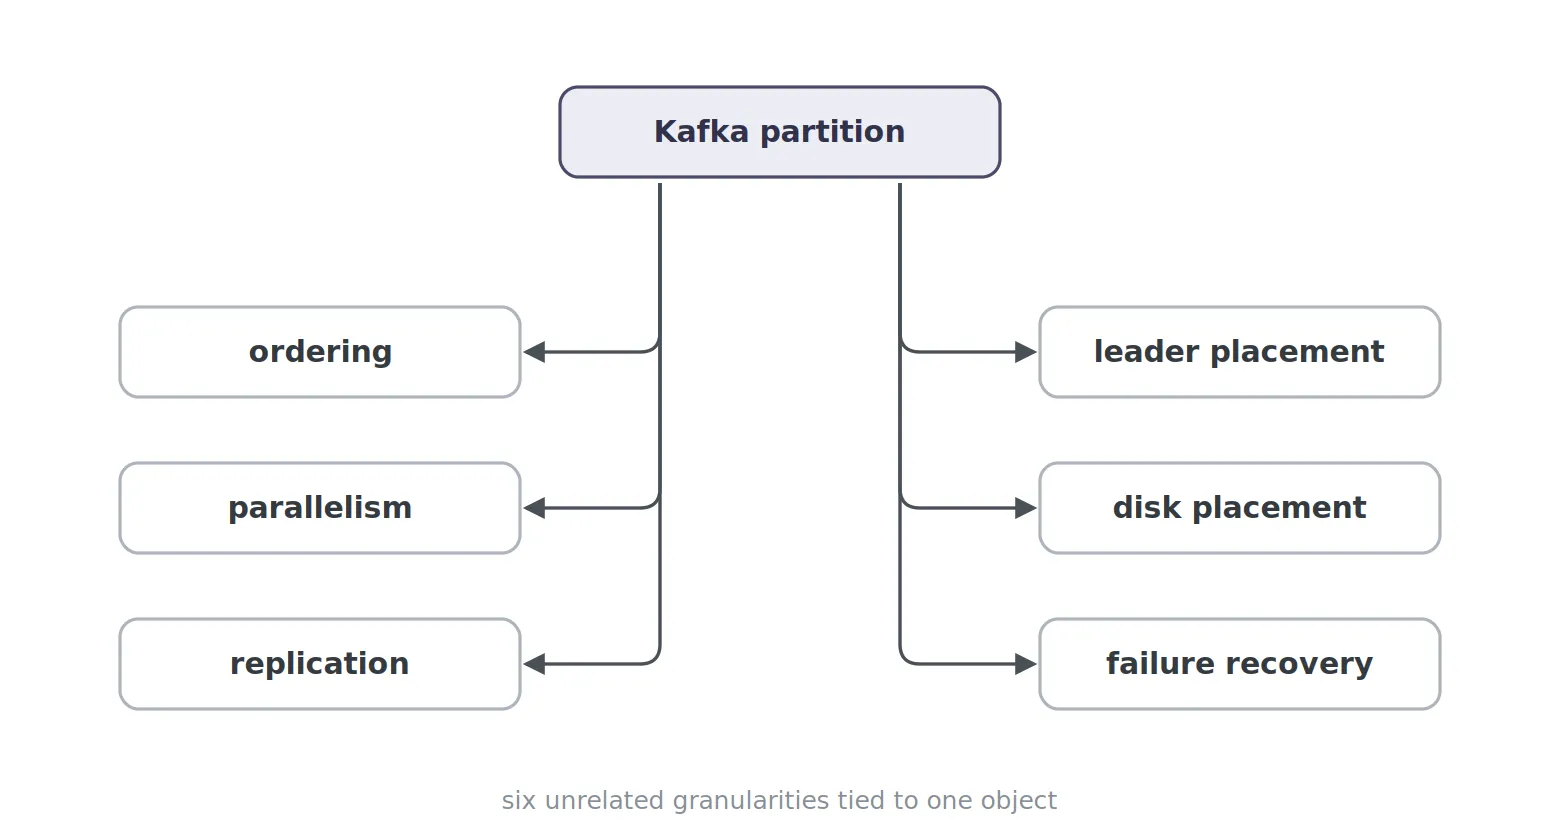
A topic with twelve partitions consists of twelve ordered logs. Every one of them has a replica assignment, a leader that accepts writes, and followers that copy the data. In a typical consumer group, partitions also define how much processing parallelism is available.
LinkedIn’s write-up points to this coupling as a problem at its scale: a partition is a heavyweight unit of replication, so relocating or repairing one may involve a large amount of data.
Adding a broker means dealing with history
Imagine a cluster with three brokers, A, B, and C, that is nearing its storage or throughput limit. We add Broker D. It begins empty; making its capacity available to existing topics usually means moving some partition replicas:
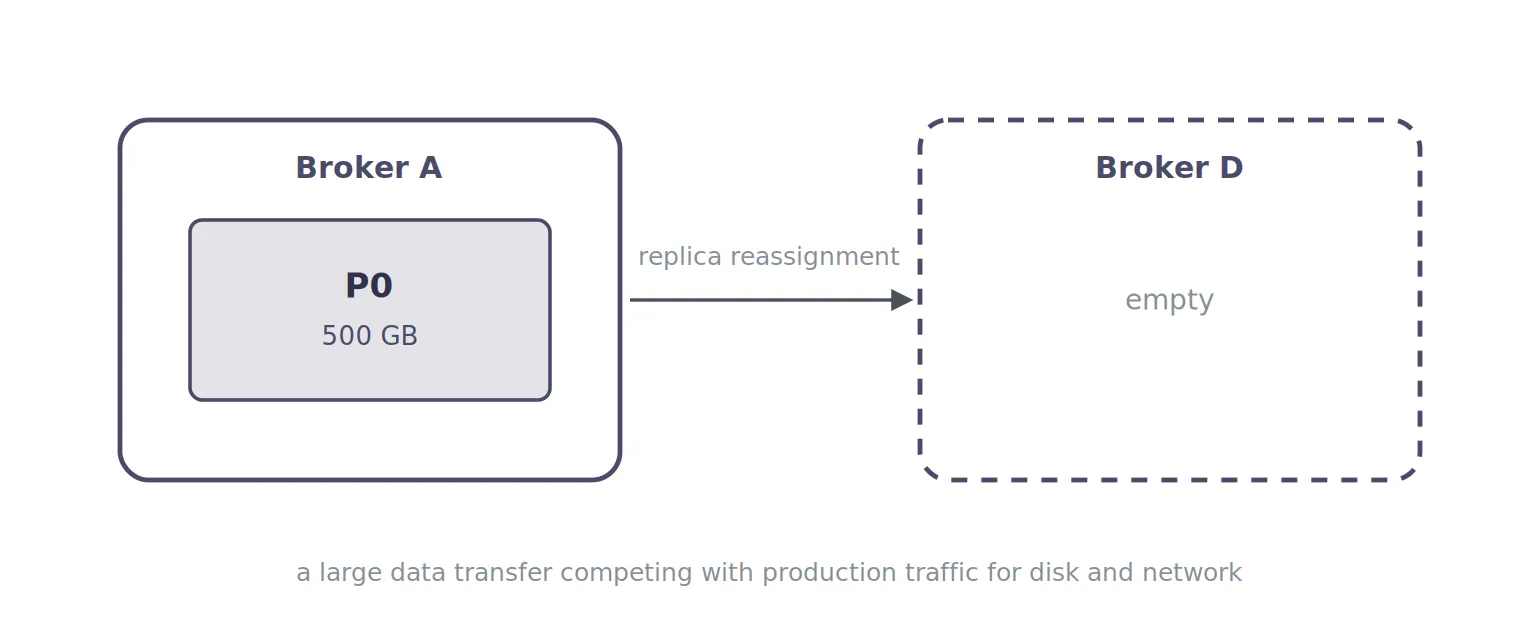
These transfers fight with production traffic for network and disk bandwidth. LinkedIn created Cruise Control to automate partition reassignment, cluster balancing, and recovery from failures. The data still needs to be transferred, frequently under a throttle that shields the live workload.
Northguard shrinks the amount of data tied to each replica assignment.
Northguard decouples the log from its replication units
In broad strokes, Northguard’s hierarchy looks as follows:
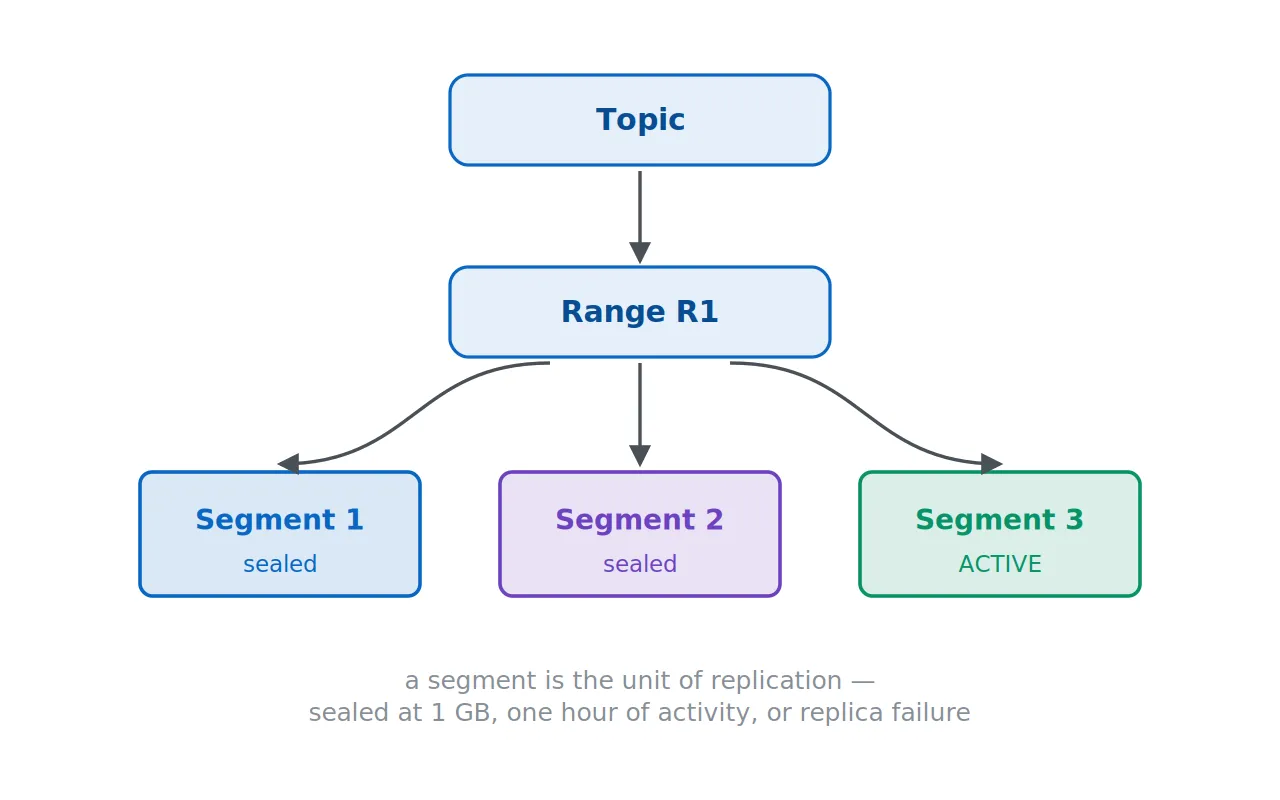
A range stands for a log spanning a contiguous part of the keyspace. It is made up of segments, each holding its own sequence of records. An active segment takes writes; a sealed one is immutable. According to LinkedIn, a segment gets sealed once it reaches 1 GB, has been active for more than an hour, or loses a replica.
The unit of replication is the segment. Kafka, too, splits partition logs into segment files, but those files usually follow the replica assignment of the partition. In Northguard, consecutive segments of the same range can have different replica sets:
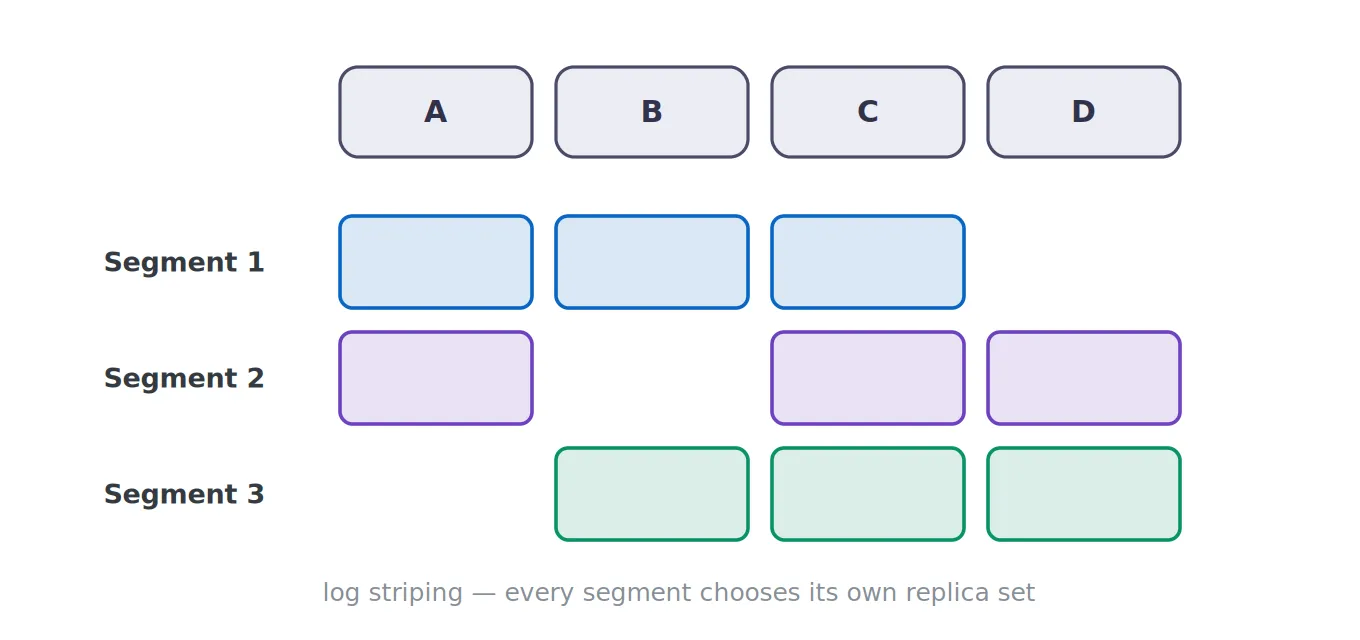
The range keeps the logical order, while its segments are spread over brokers. LinkedIn refers to this as log striping.
Leave the old data where it is
Let’s now add Broker E. Northguard can place it in the replica sets of new segments:
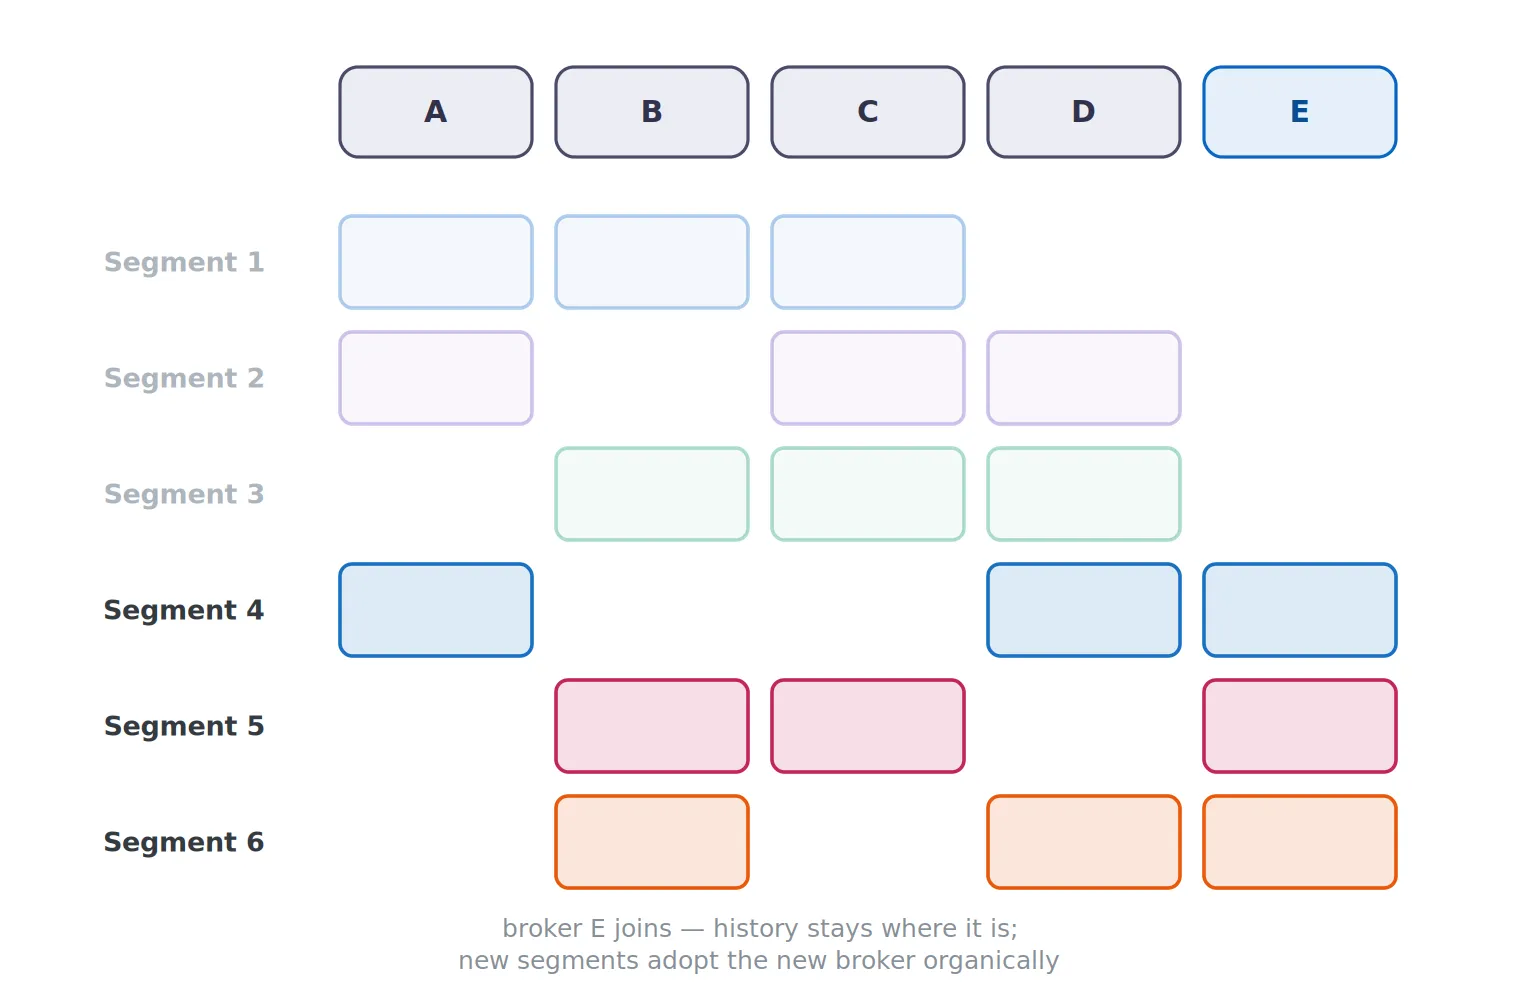
Segments that already exist can stay put. As fresh segments get created, the allocator spreads new writes across the enlarged cluster. A new broker thus receives work without historical logs having to be copied onto it beforehand.
It also offers the allocator frequent chances to fix uneven placement. The effect builds up as segments roll over; adding a broker doesn’t redistribute retained data at once. In my view, this is the most valuable change: new capacity can begin handling new traffic without a big reassignment job running first.
Failure recovery is different too
Imagine that active Segment 42 has replicas on A, B, and C, and Broker C goes down. Northguard can seal that segment and create Segment 43 with a fresh replica set:
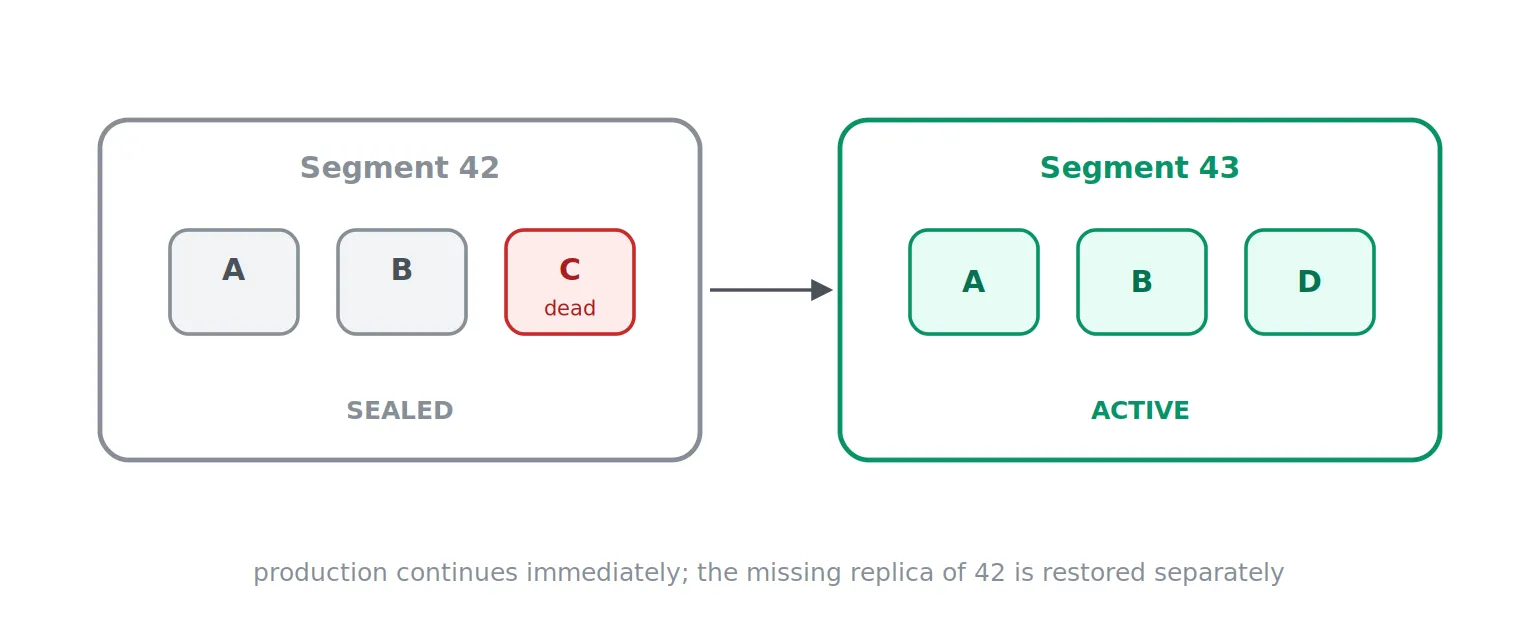
Writes go on in Segment 43, while replication of sealed segments rebuilds the lost copy of Segment 42. Fixing old data is decoupled from placing new writes.
LinkedIn attributes to this smaller replication unit the ability to keep produce available without the consistency trade-offs it had accepted in its Kafka configuration. That comparison is about LinkedIn’s own deployment decisions; it doesn’t imply that Kafka by nature forces you to give up consistency each time a broker fails.
Ranges take the place of indexed partitions
The number of partitions in Kafka also influences where keys land. With a mapping like hash(key) % number_of_partitions, adding partitions may route later records for a given key to a different partition. This has consequences for ordering, stateful processing, and keyed joins.
Northguard, by contrast, splits the keyspace into ranges that are able to split further:
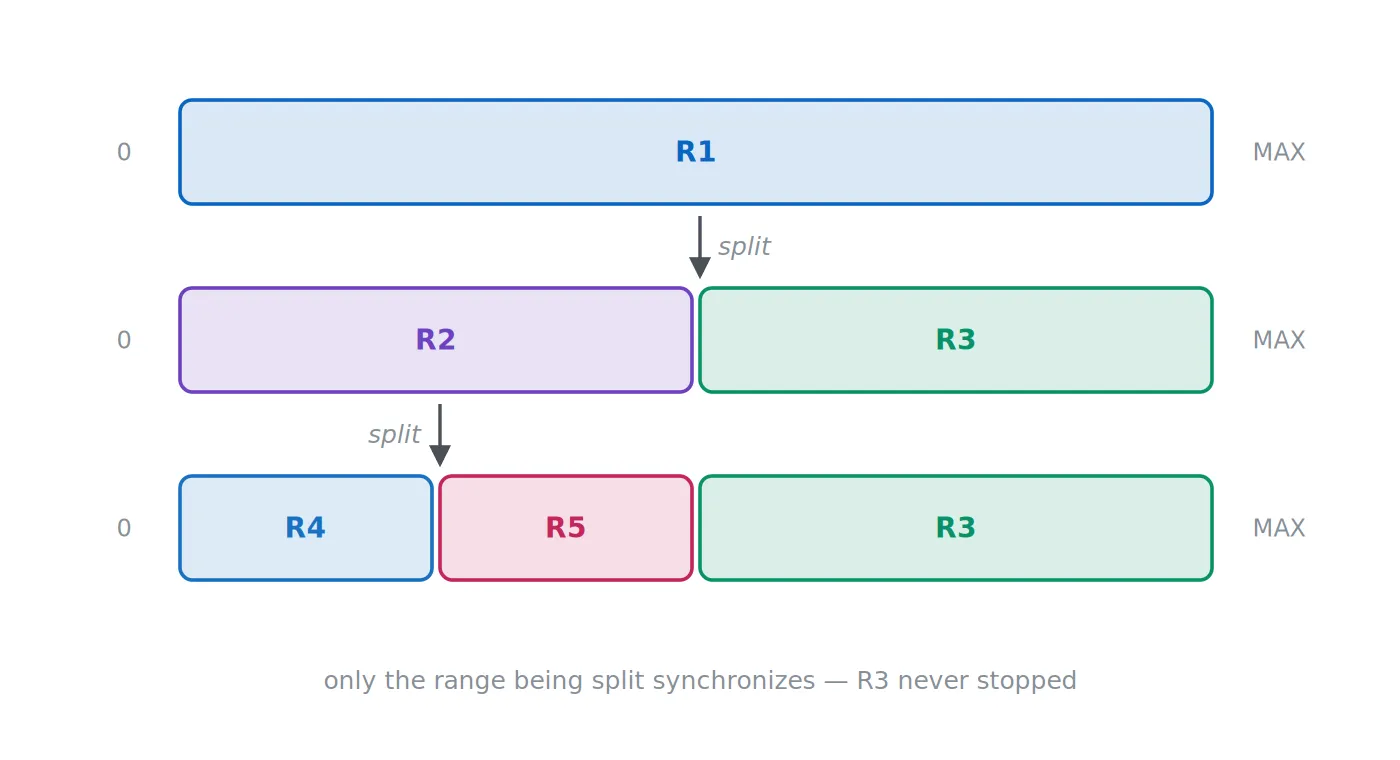
The range undergoing the split serves as the synchronization point. Producers writing to unrelated ranges can keep going. When R1 splits into R2 and R3, records in R1 come before records in either child. Merging ranges establishes an analogous ordering relationship between the parent ranges and the merged one.
This benefits stream processing as well. Take a join of orders and customers on customer ID. When their key partitioning lines up, matching records can be handled together. If one topic has ten partitions and the other sixteen, a framework may first have to reshuffle the data.
Northguard relies on buddy-style splits and merges, so ranges have aligned keyspace boundaries across topics. LinkedIn made this choice in part so that processing frameworks could skip such shuffles when joining streams on the same key.
The control plane needed changes as well
Kafka’s switch from ZooKeeper to KRaft altered how metadata is stored, but a cluster still has a single logical metadata state machine and one active controller. LinkedIn calls that centralized control plane a bottleneck once you reach millions of partition replicas.
Northguard spreads metadata over vnodes. Every vnode is a separate Raft-backed state machine headed by a coordinator. Combined, the vnodes span a hash ring:
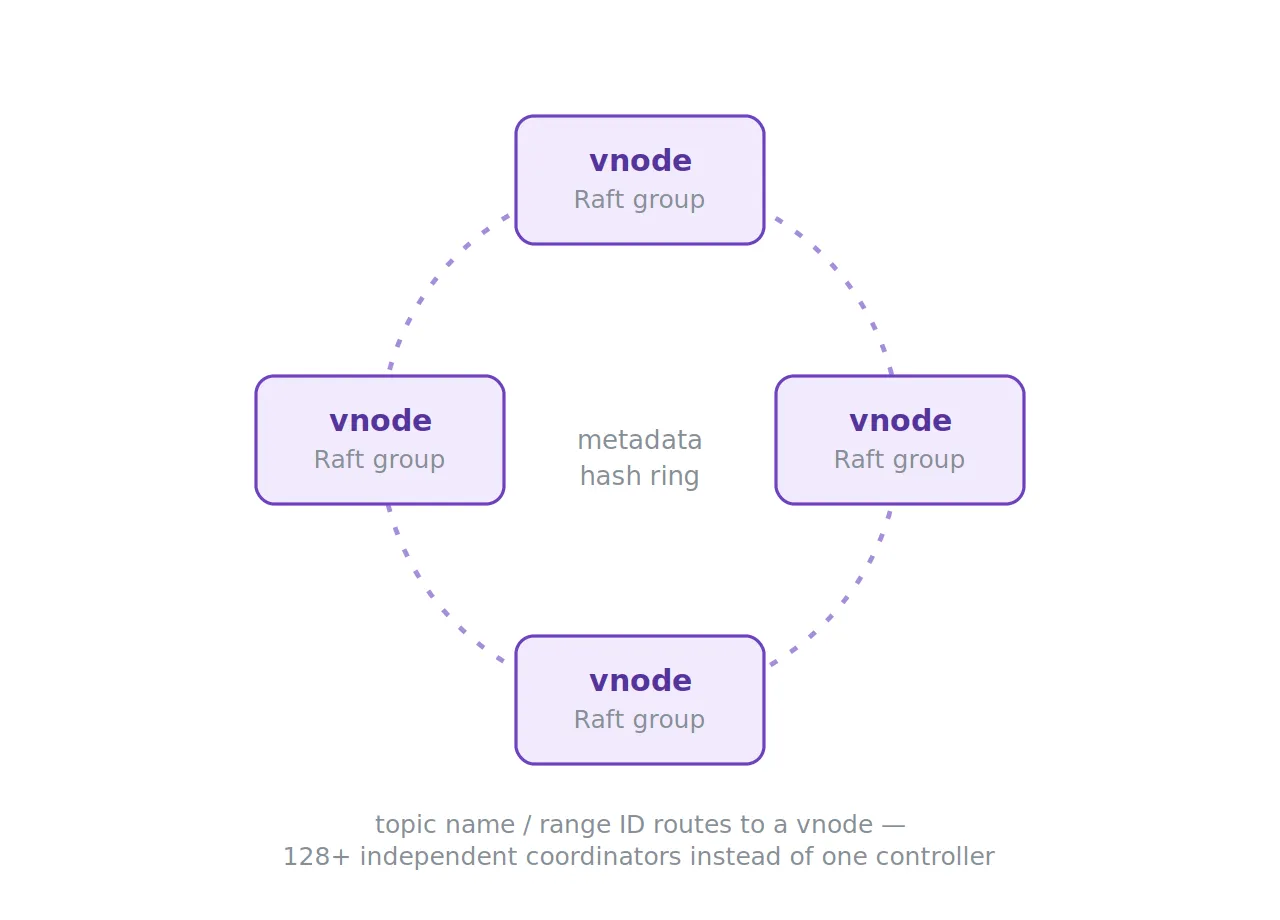
Topic metadata is assigned based on the topic name, while range and segment metadata are assigned based on the range ID. LinkedIn names this a Dynamically-Sharded Replicated State Machine, or DS-RSM, and mentions deployments running 128 or more coordinators and state machines.
Every coordinator handles the metadata belonging to its vnode, covering range splits and merges, segment state, replica assignments, and topic deletion. These operations no longer all have to go through a single metadata leader.
Not all state passes through Raft
Brokers additionally need connection addresses, broker attributes, and sufficient knowledge of the vnode ring to route requests. Northguard spreads this minimal global state via gossip, relying on SWIM for membership and failure detection.
The authoritative metadata for topics, ranges, and segments stays in the Raft-backed vnodes:
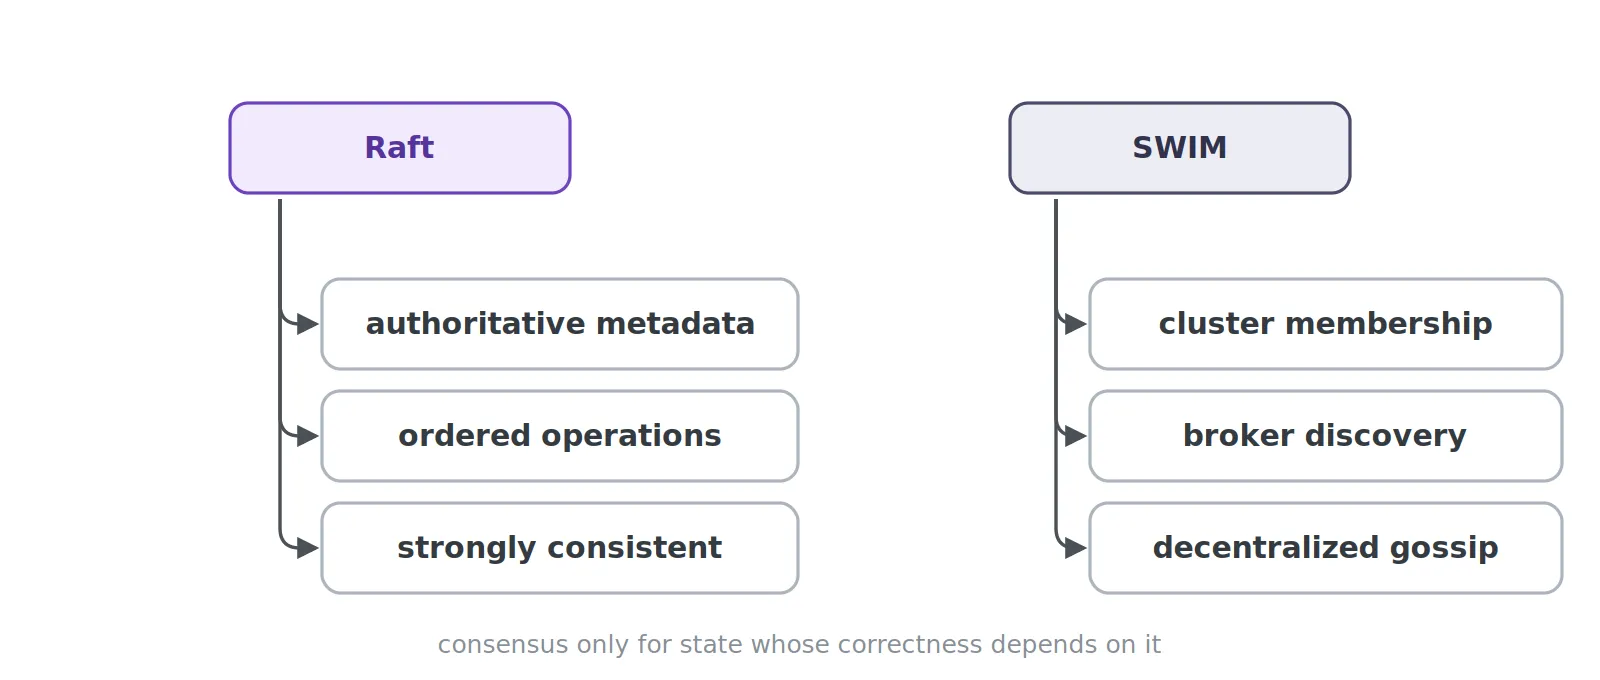
Gossip lets a broker locate the coordinator in charge of a request. The metadata change itself is decided by the coordinator’s replicated state machine. Spreading membership information and making authoritative updates thus follow different paths.
Northguard rethinks the disk path, too
Kafka depends on sequential I/O, the operating system’s page cache, and zero-copy transfer whenever it can. Northguard’s default segment store, fps store, combines a WAL, one file per segment, Direct I/O, a RocksDB sparse index, and a cache managed by the application.
The store batches appends, writes to the WAL, appends records to the segment files, calls fsync, and updates the index. Direct I/O skips the usual page-cache buffering; Northguard fills its own cache based on what it knows about active consume streams.
This hands LinkedIn more explicit control over caching. Local disks also remain in the write path, in contrast to the object-storage approach of diskless Kafka. Segment storage can be swapped out, but the published default relies on small replication units on local disks to satisfy LinkedIn’s latency requirements.
Comparing durability calls for caution
LinkedIn gives these configuration parameters for its two deployments:
| LinkedIn’s deployment | Disk synchronization | Reported sync/batch thresholds |
|---|---|---|
| Kafka | Lazy sync | 10 seconds or 20,000 records |
| Northguard | fsync on every replica before the producer is acknowledged |
10 ms, 20,000 records or 10 MB |
According to LinkedIn, Northguard hits its Kafka performance SLOs while offering those stronger disk-persistence guarantees. The announcement doesn’t include a reproducible benchmark setup or latency percentiles backing that comparison.
For the durability of acknowledged writes, Kafka typically depends on replication instead of demanding an fsync on every replica before each acknowledgement. What’s reported here is that, after redesigning its storage path, LinkedIn could afford the stricter sync requirement. This doesn’t prove that Kafka has an inherent durability limit, nor that Northguard is faster in general.
Produce is a stream rather than a series of independent RPCs
Metadata operations rely on regular request-response calls. Produce, consume, and replication rely on sessionized streaming protocols.
A producer performs a handshake with the leader of the active segment and then pipelines appends inside a window that caps the amount of data in flight. The broker may acknowledge several appends at once, but only once their records have been committed. Consume runs the data flow in the opposite direction, with the client in control of the window; replication follows the same streaming model.
A new protocol also brings a migration challenge. Thousands of applications already rely on Kafka clients and know which physical cluster stores their topics. They need an additional abstraction before the storage underneath can change transparently.
Xinfra virtualizes Pub/Sub
Xinfra sits between the applications and the log storage underneath them:
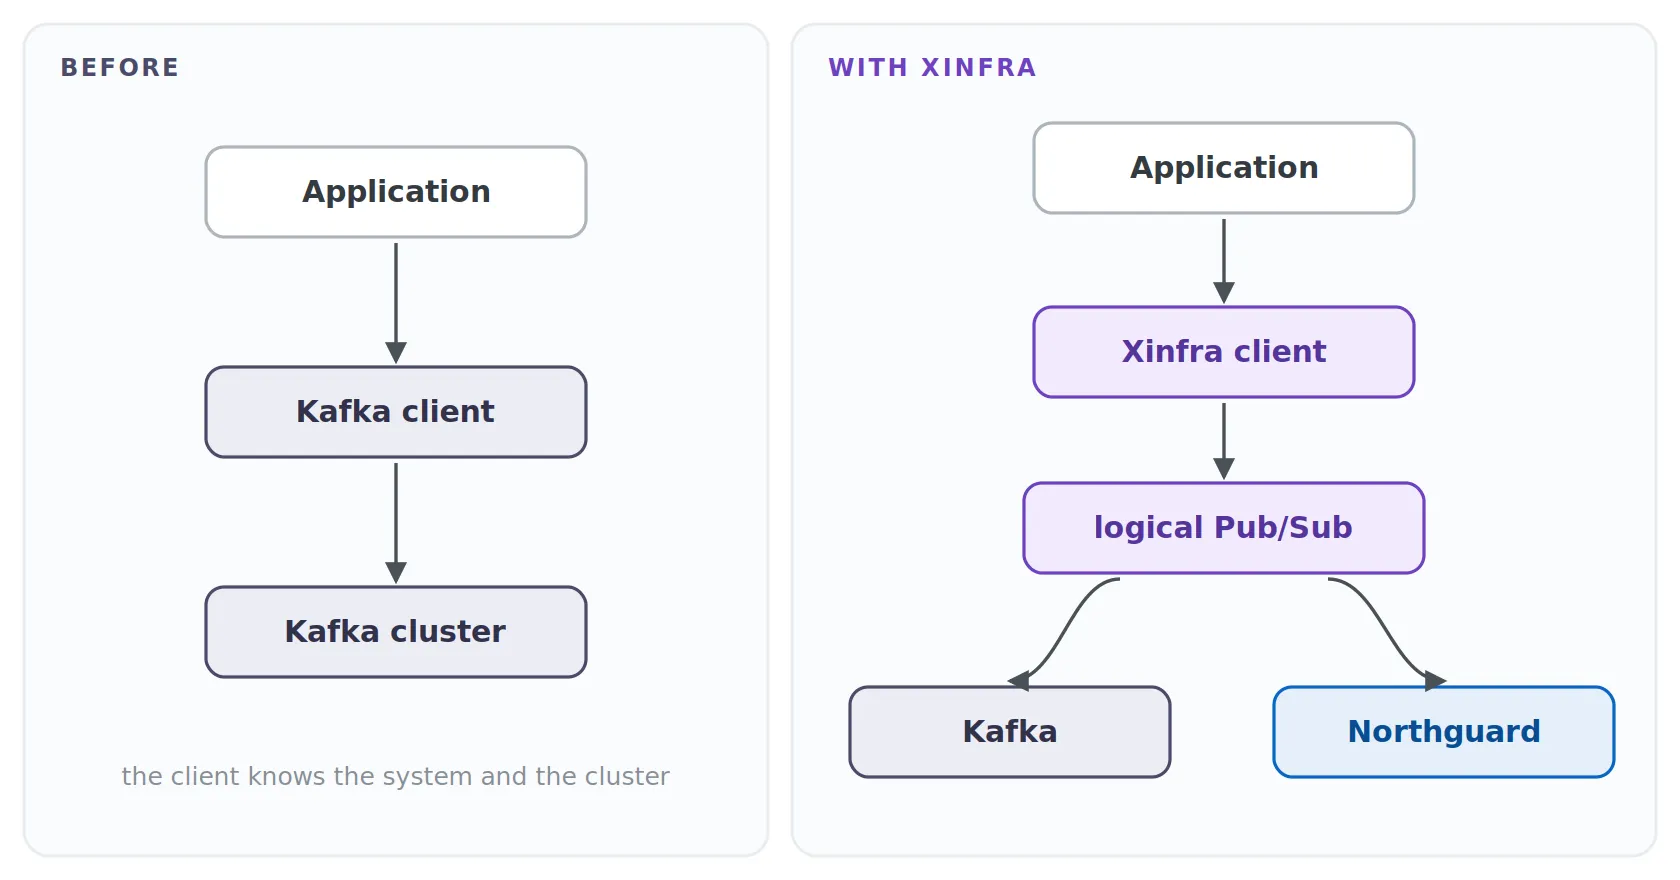
Applications talk to Xinfra clients through a unified API. A topic can be moved between physical clusters, or between Kafka and Northguard, while keeping its logical name. This requires adopting the Xinfra client; existing Kafka clients don’t get that layer of indirection for free.
At the time of the June 2025 announcement, LinkedIn said that over 90% of its applications were using Xinfra clients.
Topics have epochs
An Xinfra topic tracks changes to its physical storage by means of epochs:
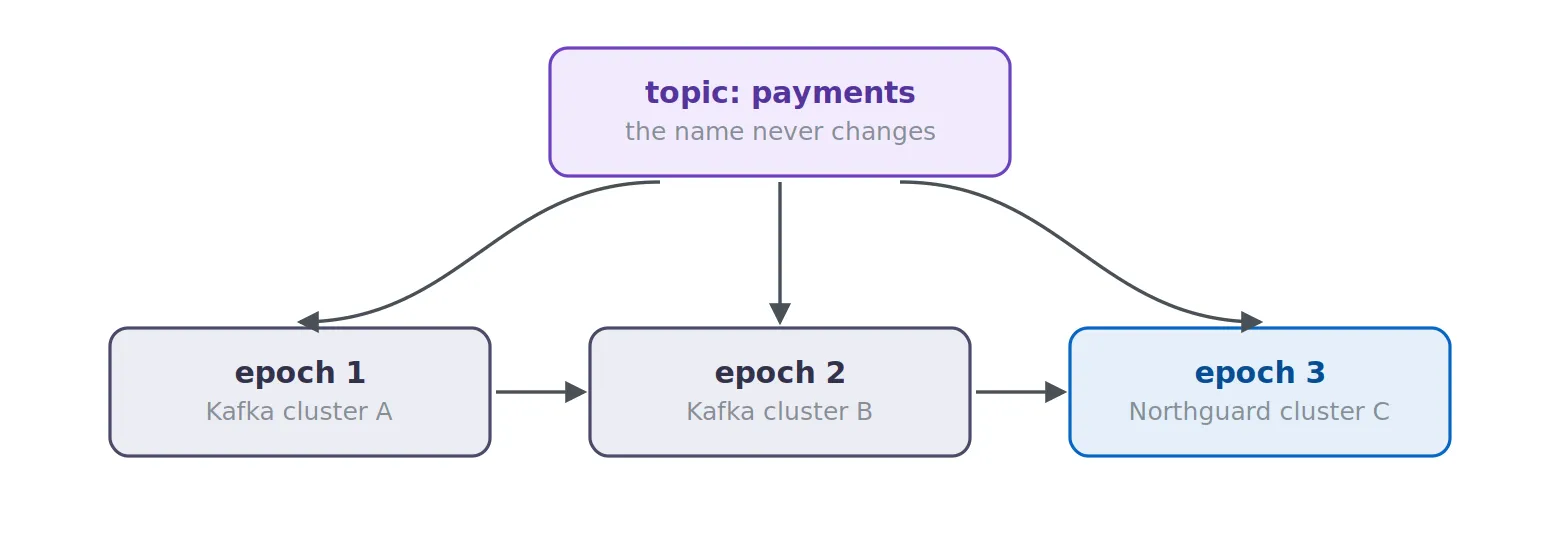
The application can go on using payments while one epoch resides in Kafka and a subsequent one in Northguard. Every epoch holds the shards making up that version of the topic. Clients get the physical mapping from Xinfra metadata rather than having it hardcoded in the application configuration.
From Kafka to Northguard without halting everything
Xinfra sets up a new epoch at the destination. Producers are migrated first and, for a while, write to both systems:
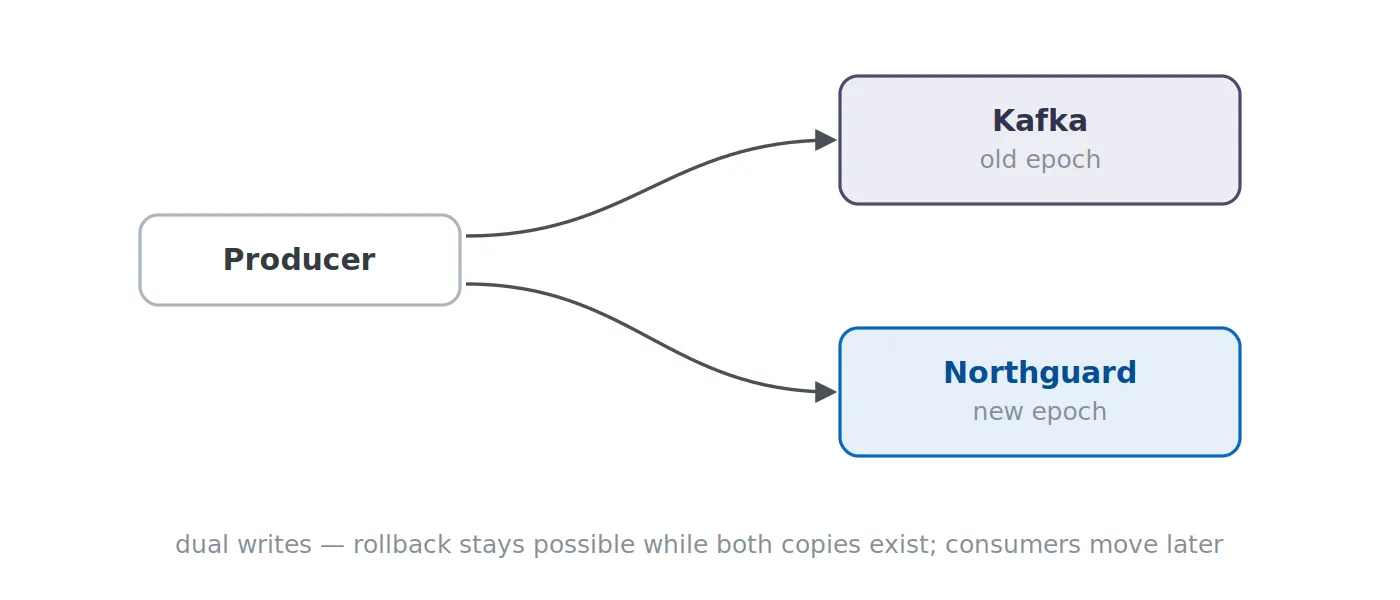
Thanks to dual writes, a failed migration can be rolled back. Consumers are moved afterwards; when the transition is complete, dual writes end. Consumers are still able to read earlier epochs until retention deletes their data. LinkedIn says applications keep running and ordering guarantees are preserved for the whole transition.
By June 2025, LinkedIn said it had migrated thousands of topics handling trillions of records per day. Kafka and Northguard were still operating in parallel. These numbers reflect the state of the rollout when the report was published, not a full replacement of Kafka.
Xinfra also conceals the cluster boundary
Xinfra is able to group topics living in different physical clusters into a single virtual cluster:
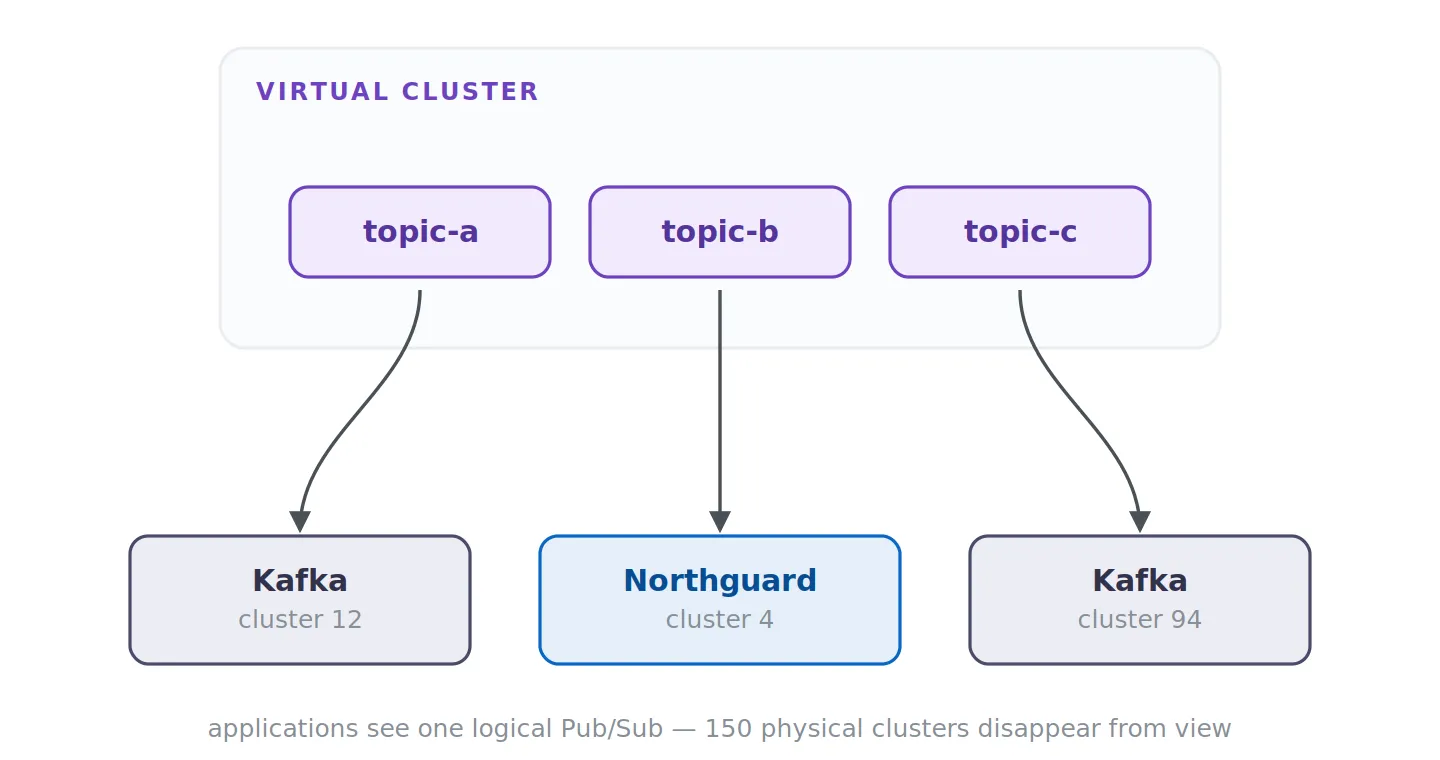
A consumer can subscribe to these topics via the same logical environment, even if they are stored in separate systems. This allows LinkedIn to handle workloads bigger than a single physical cluster and to change where topics are placed without forcing every application to keep track of the topology.
The complexity didn’t go away
The application API gets simpler, but Xinfra brings additional infrastructure for the platform team to run:
- MySQL keeps the mappings of virtual and physical topics and clusters.
- ZooKeeper takes care of membership, leadership, and consumer-group allocation.
- Vitess keeps consumer checkpoints, while Couchbase serves as a low-latency cache.
With LinkedIn’s approximately 150 clusters, centralizing this work may well pay off. With two Kafka clusters, running the virtualization layer could cost more than the problem it addresses.
Maybe what LinkedIn really outgrew was the partition
Northguard and Xinfra split responsibilities on three levels. Ranges determine the logical keyspace and ordering, while segments determine replication and placement. Separate Raft groups share the work of metadata management. Xinfra decouples the topic that applications see from the physical system that stores it:
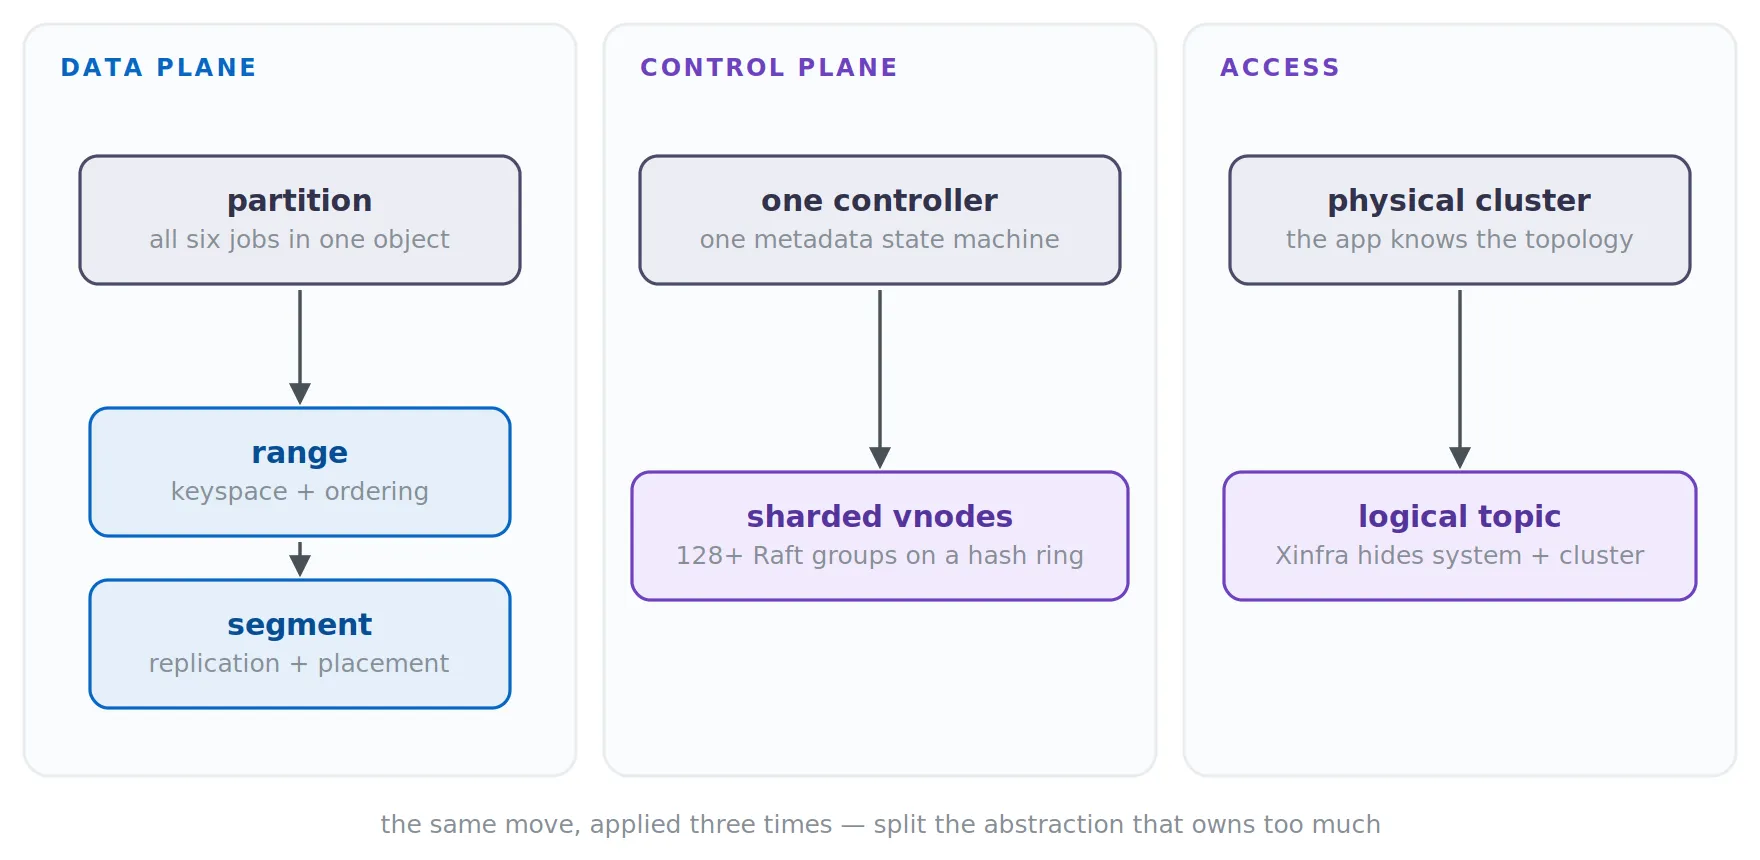
Seeing this as LinkedIn outgrowing the partition is my own interpretation. Its write-up names several specific problems: coarse replication units, indexed partitions, balancing, and centralized metadata. What ties them together is how many operations rely on the same placement and ordering boundaries.
Kafka had already taken LinkedIn to a remarkable scale. For a setup with forty topics and six brokers, building Northguard and Xinfra would be an extremely costly answer to everyday operational issues. The question worth asking is which costs in your own system stem from the workload, and which stem from tying ordering, replication, placement, and parallelism to a single partition.